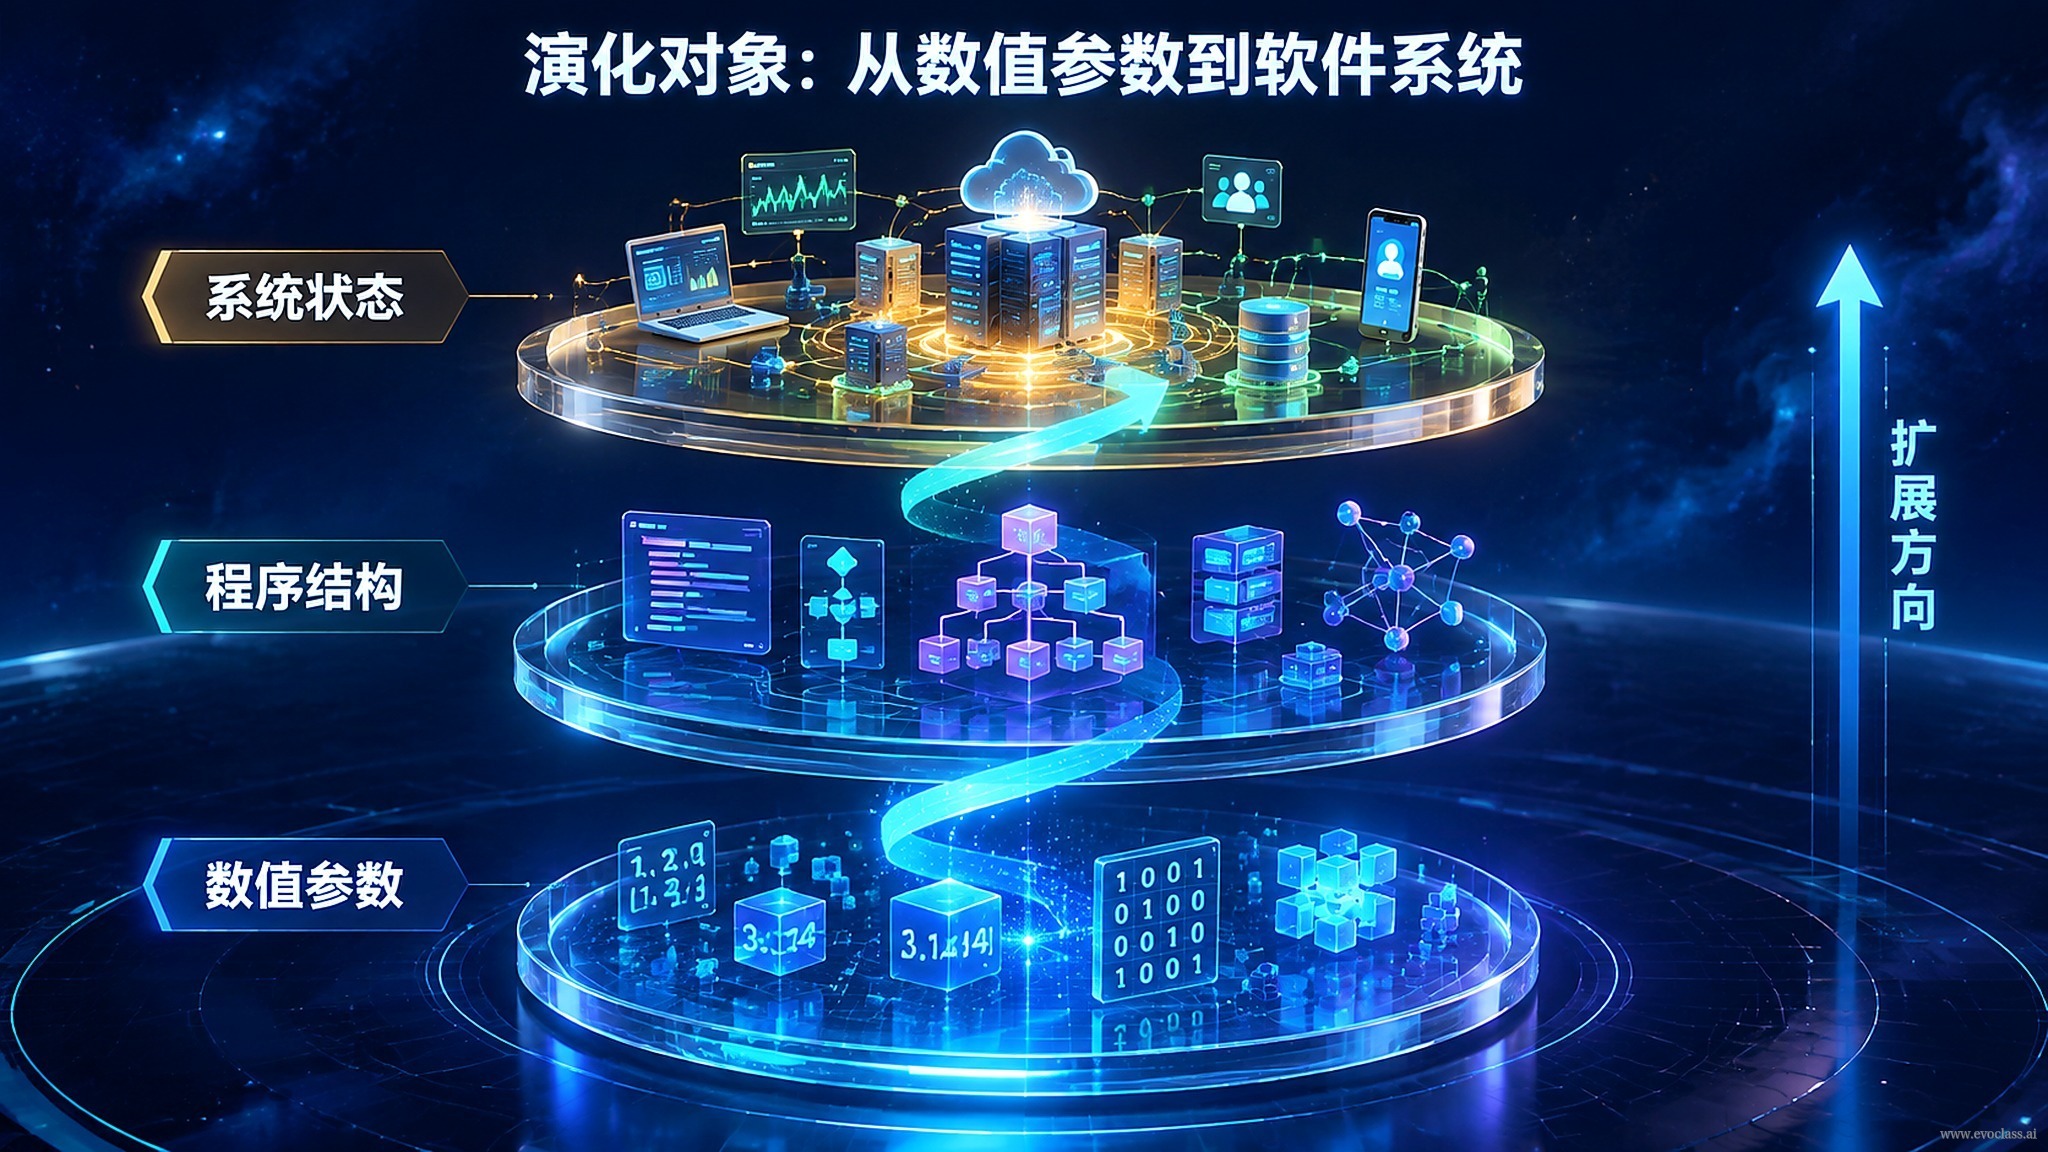
In the early practice of evolutionary computation, the objects being "evolved" were almost alwaysnumerical parameters—learning rate, batch size, regularization strength, weight initialization. The search space was just a set of numbers, and evaluation meant one training run plus one validation run. As compute scale grew and large model capabilities matured, the objects that can be evolved expanded markedly: programs, model architectures, algorithmic mechanisms, and even an entire block ofsoftware engineering state(configurations, dependency versions, interface contracts, deployment and runtime strategies).
This expansion path can be represented as a clear arrow chain: numerical parameters → programs and model architectures → software engineering state and system-level candidates. The further to the right the level is, the stronger the expressiveness and the more types of change it can cover—making system-level evolution possible.
Three Levels of Evolutionary Objects, Each with Different Costs
- Numerical parameter level: A candidate is just a set of numbers—cheap to generate and quick to evaluate—but it can only answer "how well it is tuned," and cannot supply a mechanism that was missing to begin with.
- Program and model architecture level: Candidates are network architectures, operator compositions, prompt workflows, or code patches; changes alter "what the system can do," not just "how accurately it does it."
- Software engineering state level: Candidates are configurations, dependency versions, interface contracts, and deployment strategies, directly determining whether the system can run stably and be reproduced.
Shifting Focus: From "How to Generate Candidates" to "How to Execute and Evaluate"
When candidates go from numbers to programs, "generating candidates" is no longer the bottleneck: large models can mass-produce structures, mechanisms, and patches. What truly determines whether evolution is effective isthe execution and evaluation mechanism—whoever can actually run the candidates and, within acceptable cost, judge whether they are worth keeping.
The stronger the expressiveness, the heavier the evaluation burden. A numerical parameter only needs one training run to be scored; a code patch, however, requires sandbox isolation, regression testing, and benchmark comparison before it can answer three questions: Is it truly effective? Does it introduce risk? Can the results be reproduced? Sandboxes, regression tests, and benchmarks are precisely the engineering devices used to constrain cost, risk, and reproducibility—and they allow changes to be reliably kept or eliminated.
Engineering Trade-offs: More Candidates Does Not Mean Better Evolution
In team practice, a common path is to first tune learning rates and hyperparameters, then gradually expand to searching network architectures, operator compositions, prompt workflows, or code patches. Each expansion of a level requires answering in step: How much compute and time will evaluation cost? Will failed candidates contaminate the existing system? Can the same results be reproduced next time? Only by balancing expressiveness, evaluation cost, reproducibility, and safety does system-level evolution truly become feasible.
Three-Level Expansion of Evolutionary ObjectsThe arrow chain in the figure goes from numerical parameters to programs and model architectures, then to software engineering state and system-level candidates: the further right, the more objects can be changed and the stronger the expressiveness. But the cost rises accordingly—numerical parameters only need one training run to score, whereas code patches require sandbox isolation, regression testing, and benchmark comparison to judge effectiveness, risk, and reproducibility.