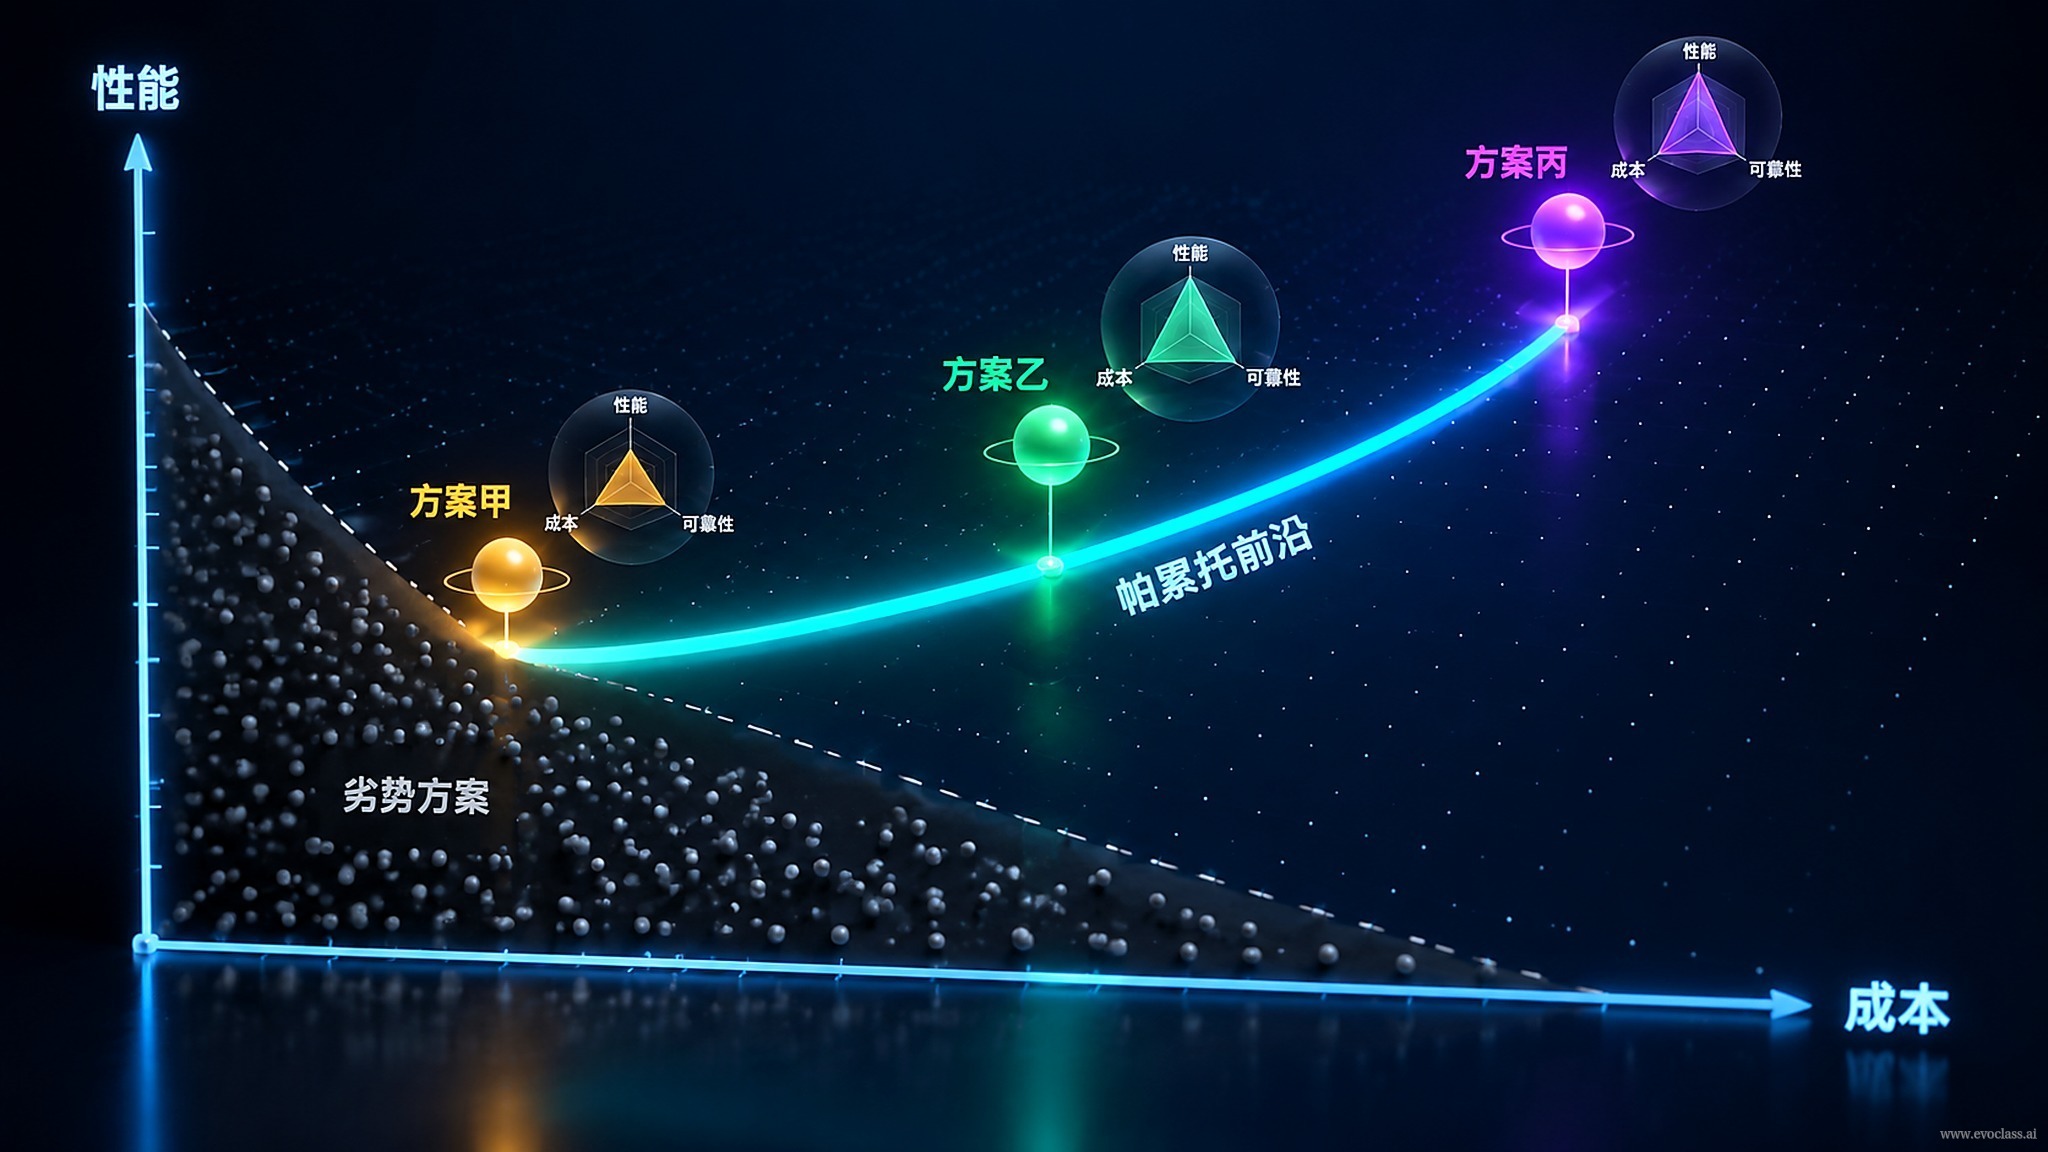
In the real world, optimization problemsrarely have just one objective, and rarely have just one answer. A single system often has to balance performance, latency, energy consumption, and cost at the same time; these objectives pull against one another, and improving one frequently comes at the expense of another. So the value of EvoX is not in converging faster to some “single optimum,” but inkeeping a diverse set of candidate solutions, so researchers can weigh gains against costs within the constraints and keep exploring.
Why a single optimal solution is rarely possible in the real world
- Objectives and constraints shift with the scenario: for offline evaluation, for mobile devices, and for high-concurrency online services, the top priorities are completely different—one configuration is unlikely to win in all three.
- Constraints come with hard boundaries that cannot be broken: end-to-end latency caps, per-inference cost budgets, VRAM and power limits, and so on are boundaries every candidate must satisfy—not bargaining chips that can be traded away for “better overall” results.
- Multiple objectives pull against one another: higher accuracy → more computation and energy → higher latency and cost; conversely, cutting latency → you often have to accept lower accuracy. There is no free improvement.
Non-dominated solutions and the Pareto front
Only when two candidates cannot be ranked as absolutely better or worse do they form a genuine space of choices. The test is straightforward: if one candidate is no worse than another on every objective and better on at least one, then the other candidate isdominatedand can be eliminated in the next round; otherwise, neither dominates the other and both should stay in the candidate set. All mutually non-dominated candidates together form the Pareto front—it fully preserves the trade-off relationship of "how much of one objective must be sacrificed to improve another."
Key questions for the researcher
- What can be changed?—The model architecture, distillation strategy, quantization bit width, batch size, or service scheduling policy?
- What feedback shows that a change actually worked?—Offline accuracy, online latency percentiles, unit cost, or resource utilization curves?
- Which constraints cannot be broken?—Hard latency caps, cost budgets, and compliance and safety boundaries.
- Is the comparison fair?—Whether candidates are compared on the same hardware, under the same traffic distribution, and using the same evaluation criteria.
- Are the results sufficient to support the conclusion?—Whether the sample size and online traffic coverage are adequate, and whether the conclusion is reproducible.
- What to keep and what to drop in the next round?—Eliminate dominated solutions and keep the mutually non-dominated, diverse candidates.
Multi-Objective Trade-offs and the Pareto FrontThe figure compares candidates across multiple dimensions—performance, latency, energy, and cost: if one candidate is no worse on every objective and better on at least one, the other is a dominated solution and can be eliminated in the next round. Mutually non-dominated candidates together form the Pareto front, fully preserving the trade-off relationship in which improving one objective requires sacrificing another.