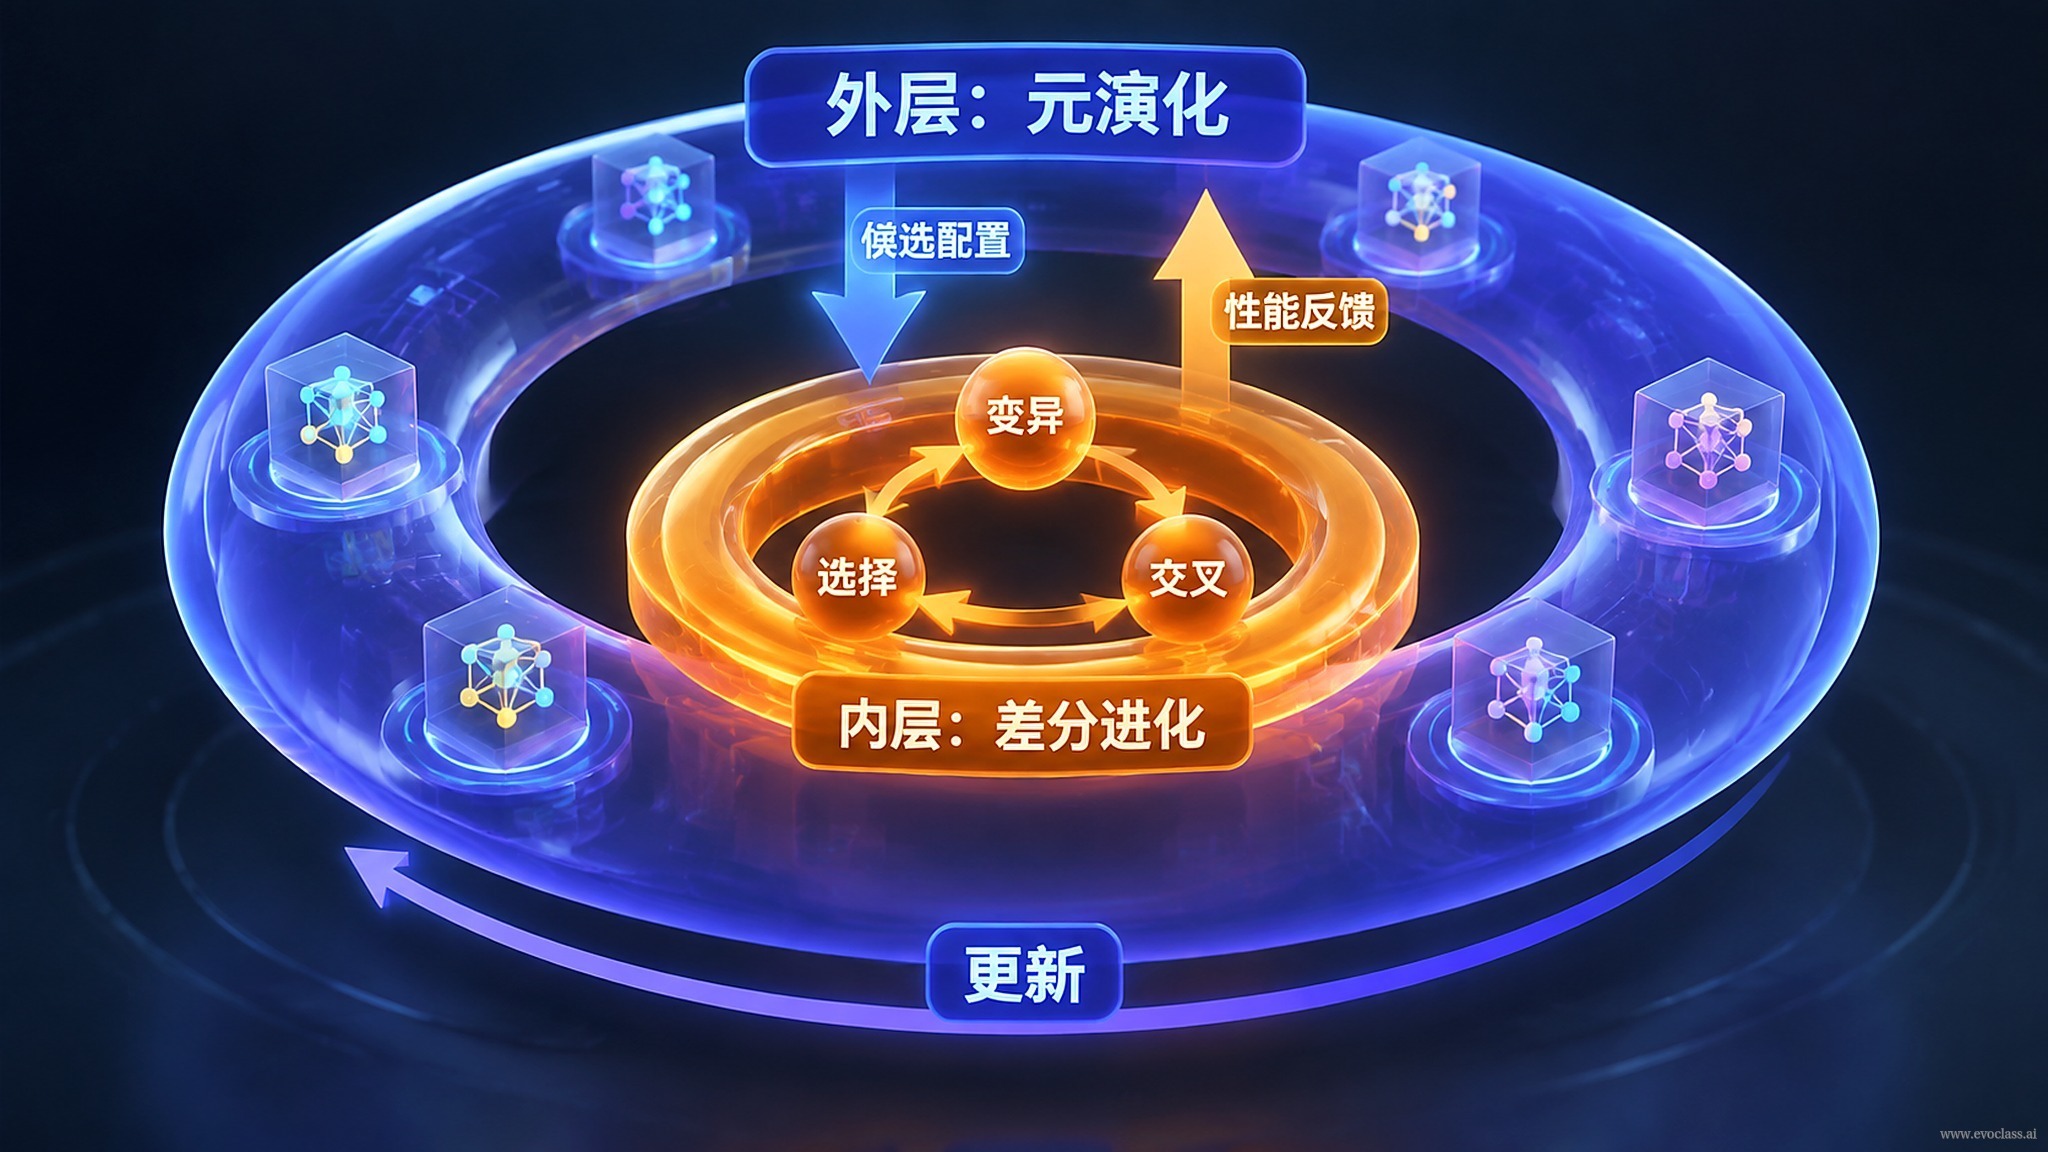
In the previous lesson, evolutionary systems accumulated capability through the closed loop of "generation–evaluation–selection–inheritance." This lesson pushes that idea one layer deeper: instead of merely having algorithms solve problems, we have algorithms improve algorithms.MetaDE is exactly this kind of nested evolutionary architecture—it splits Differential Evolution (DE) into an inner and an outer layer, turning "algorithms optimizing algorithms" into an executable computational process.
1. Division of Labor: Who Solves, Who Evolves
MetaDE organizes DE into an inner and an outer layer, and the two layers operate on completely different objects:
- Inner DE (task layer): This layer targets the real optimization task, maintains a population of candidate solutions, and repeatedly performs mutation, crossover, and selection to gradually approach high-quality solutions for the task. It answers the question: "How well is this problem being solved?"
- Outer DE (meta layer): This layer targets the algorithm itself. Each individual in the population is not a task solution but a complete "mutation strategy + parameter" configuration—for example, which mutation scheme to use and what values to assign to the scaling factor and crossover probability. It answers the question: "How well does this algorithm configuration perform?"
Therefore, the outer layer does not directly optimize task variables—those are always handled by the inner layer. What the outer layer changes is simply the inner layer's "playbook."
2. The Interactive Loop: Configuration Delivery and Performance Feedback
The two layers are coupled through a bidirectional channel, forming a closed loop: the outer layer first produces a set of algorithm configurations and delivers them (→) to the inner layer; the inner layer runs on the task according to those configurations, then returns task performance (→) to the outer layer; the outer layer uses this to retain and recombine better-performing configurations, then produces the next round of configurations. The entire process can be summarized as: outer configurations → inner solving → task performance → outer update, repeating cyclically.
This closed loop brings a key property: the inner algorithm's mutation strategies and parameters are no longer set once by a human and fixed forever, but are continuously rewritten as the outer search proceeds—giving the algorithm a channel for self-improvement.
3. Prerequisites for Execution: Parallelism and Cost Trade-offs
The nested structure is not without cost. Every outer evaluation requires fully running one configuration through the task, which significantly amplifies evaluation cost; the larger the outer population, the higher the total overhead. This is precisely why MetaDE relies on GPU parallelism: multiple inner configurations can be evaluated simultaneously, dramatically compressing the time required for a single outer iteration, making nested meta-evolution practically executable in engineering terms. Conversely, if available parallel resources are insufficient, reducing the outer-layer size or lowering inner evaluation precision is often more realistic than blindly expanding the search.
MetaDE Nested Evolutionary ArchitectureThe diagram illustrates MetaDE's inner and outer two-layer structure: individuals in the outer meta-layer population are complete mutation strategy and parameter configurations responsible for evolving algorithm settings; the inner task layer maintains a candidate solution population according to the configurations delivered by the outer layer and solves the real optimization task. The two layers are coupled through a bidirectional channel—the outer layer delivers configurations, the inner layer returns task performance, and the outer layer uses this to retain and recombine superior configurations, forming a closed loop of algorithmic self-improvement.