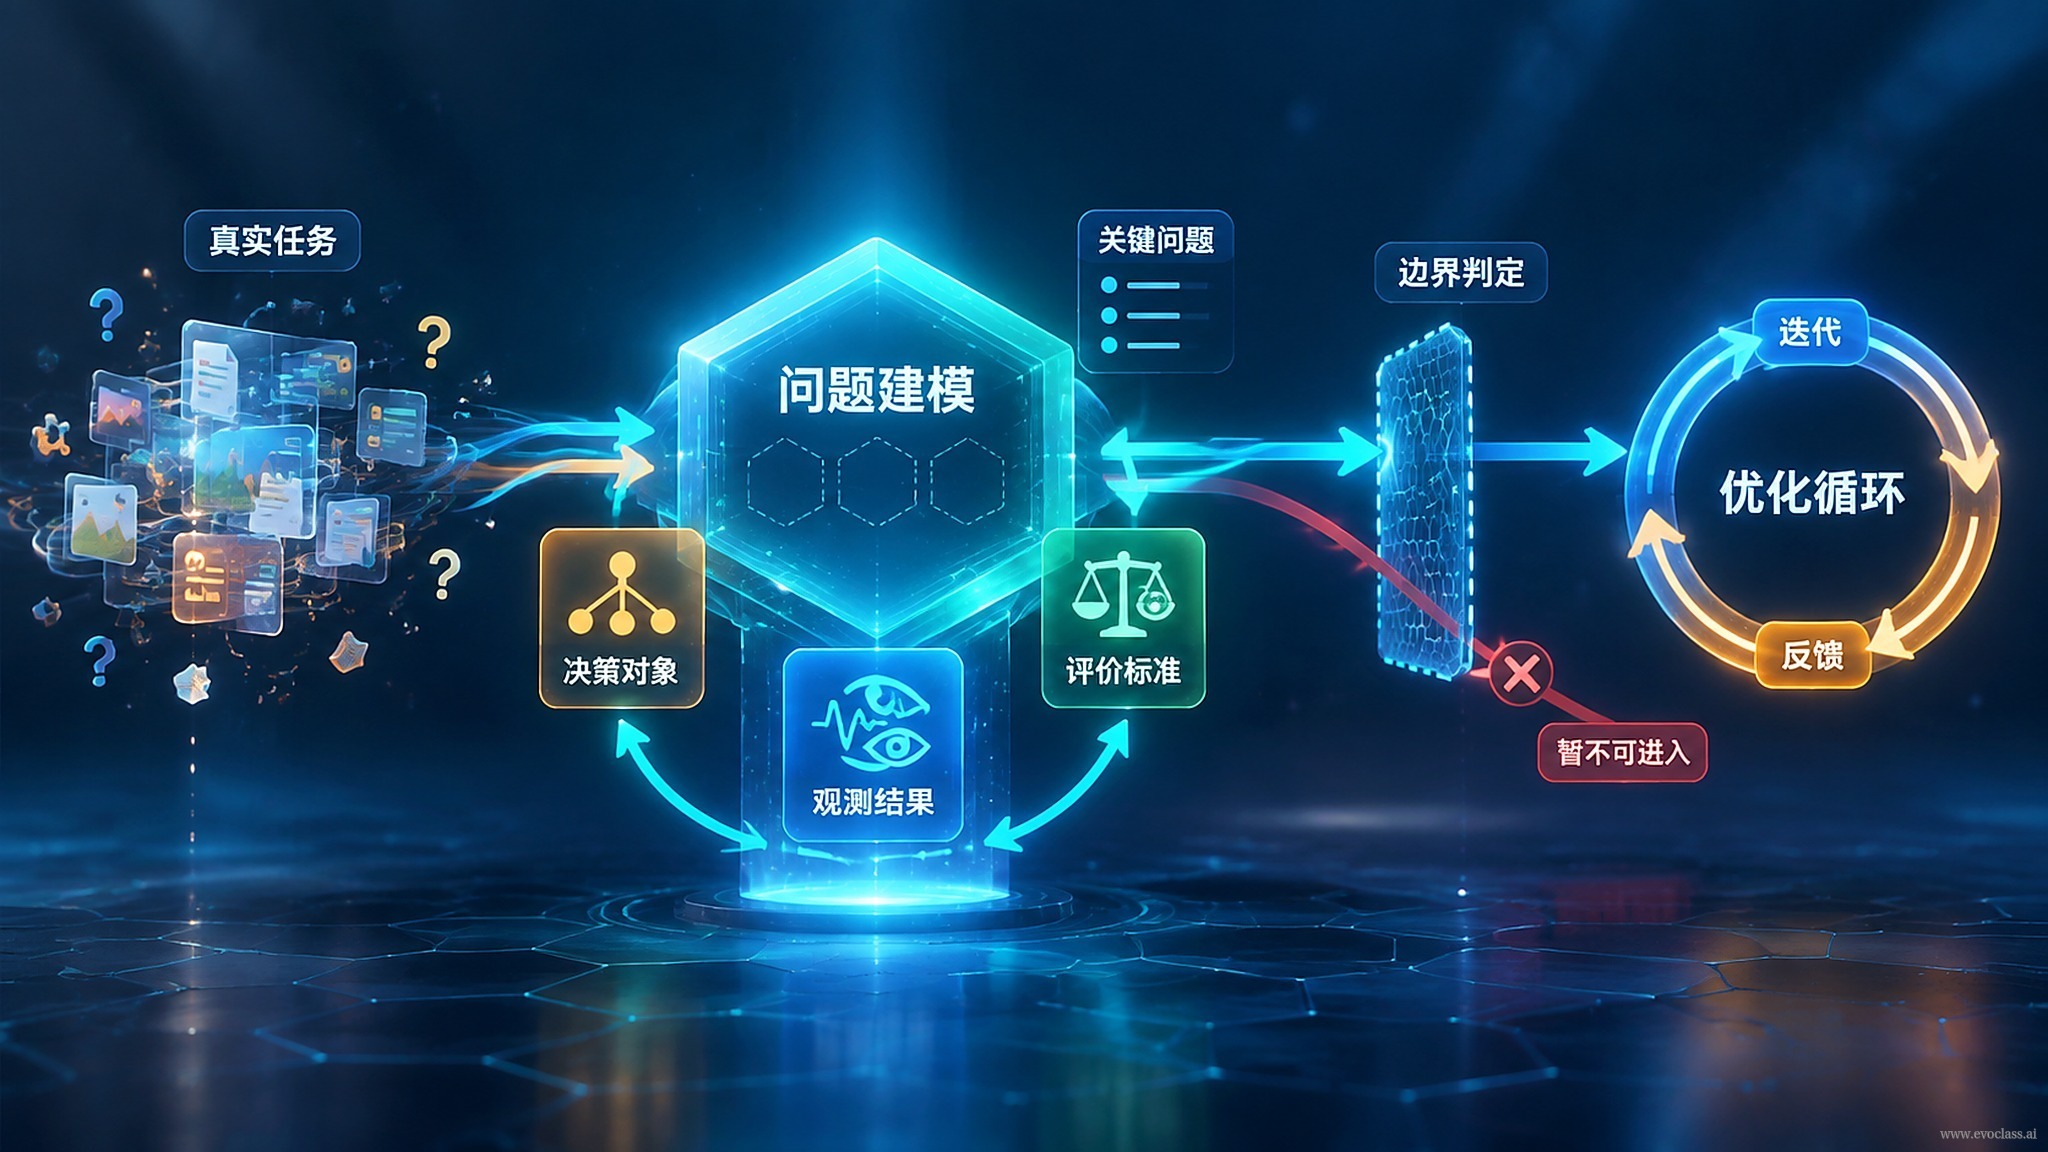
When integrating a real task into EvoX, the hard part is never "swapping in a stronger evolutionary operator" — it is first defining the task'scontract: which objects are allowed to change (the search space), which outcomes can be observed (the feedback channel), and which changes should be retained (the evaluation criteria). Together, these three boundaries determine whether the evolutionary loop can hold — so they must be settled before launch, not probed tentatively as evolution proceeds.
1. The boundary of changeable objects: defining the search space
Explicitly declare the decision variables and structure (the genotype), together with their mapping to real outputs (the phenotype), while marking the read-only environment, data, interfaces, and hardware constraints. If the boundary is too broad, a flood of invalid candidates enters the search; if too narrow, there is no room to evolve at all. Take a data processing pipeline as an example: what can change is the choice of operators, their execution order, and their hyperparameters, whereas the structure of the input data and compliance constraints are read-only.
2. The boundary of observable outcomes: opening up the feedback channel
Every candidate must be able to produce a signal that a program can capture. Specify the observation channel, latency, noise level, and reproducibility. Dimensions that cannot be observed cannot serve as a basis for optimization — only for after-the-fact explanation. Writing unobservable things into the fitness function only drives evolution toward noise.
3. Evaluation criteria and retention rules: defining what is worth keeping
Define the fitness or objective vector, the constraints, and the feasibility test; state whether scores are compressed into a single value or retained as a multi-objective Pareto front; and specify how failed, crashed, or timed-out candidates should be penalized, repaired, or stopped early. Once the evaluation criteria are fixed, they effectively determine the direction in which evolution will converge.
4. Evaluation cadence: parallelism, cost, and budget
Confirm whether evaluations can run in batch or asynchronously, along with the per-evaluation cost and the total budget. Parallelism and single-run latency directly determine the cadence of the evolutionary loop and how many generations are affordable: serial evaluation stretches the loop, drastically reducing the affordable number of generations, while batch or asynchronous evaluation can speed up iteration considerably. Stopping rules and budget must be spelled out too — specify the evaluation budget, convergence criteria, and stopping conditions, to both prevent unbounded compute consumption and avoid terminating a still-forming solution prematurely.
5. Evaluation credibility: beware of "optimizing the metric without solving the problem"
Three risks deserve vigilance: a mismatch between proxy metrics and the true objective, target leakage, and candidates gaming the evaluator (exploiting scoring loopholes to inflate scores). The countermeasures are to keep a held-out validation set or a human review step, and to make the evaluation process as stateless and replayable as possible so failures can be reproduced and results attributed.
6. The integration contract
Finally, wrap the task as an interface EvoX can call: input a candidate, output metrics and constraints, and ensure evaluations are as stateless and replayable as possible. Only when the contract is stable can the loop be stable. Treat the training-set score as the sole retention criterion and evolution will quickly overfit to that metric — which is exactly why the evaluation boundary must be settled before the search boundary.
Key Questions for Integrating Tasks into EvoXThe diagram centers on the three boundaries for integrating a task into EvoX: changeable objects define the search space, observable outcomes open up the feedback channel, and evaluation criteria determine what is worth keeping. It then extends to evaluation cadence, budget, and credibility, and finally distills everything into an integration contract that takes a candidate as input and outputs metrics and constraints. It emphasizes that boundaries must be settled before operators, because boundaries determine the direction of evolution.