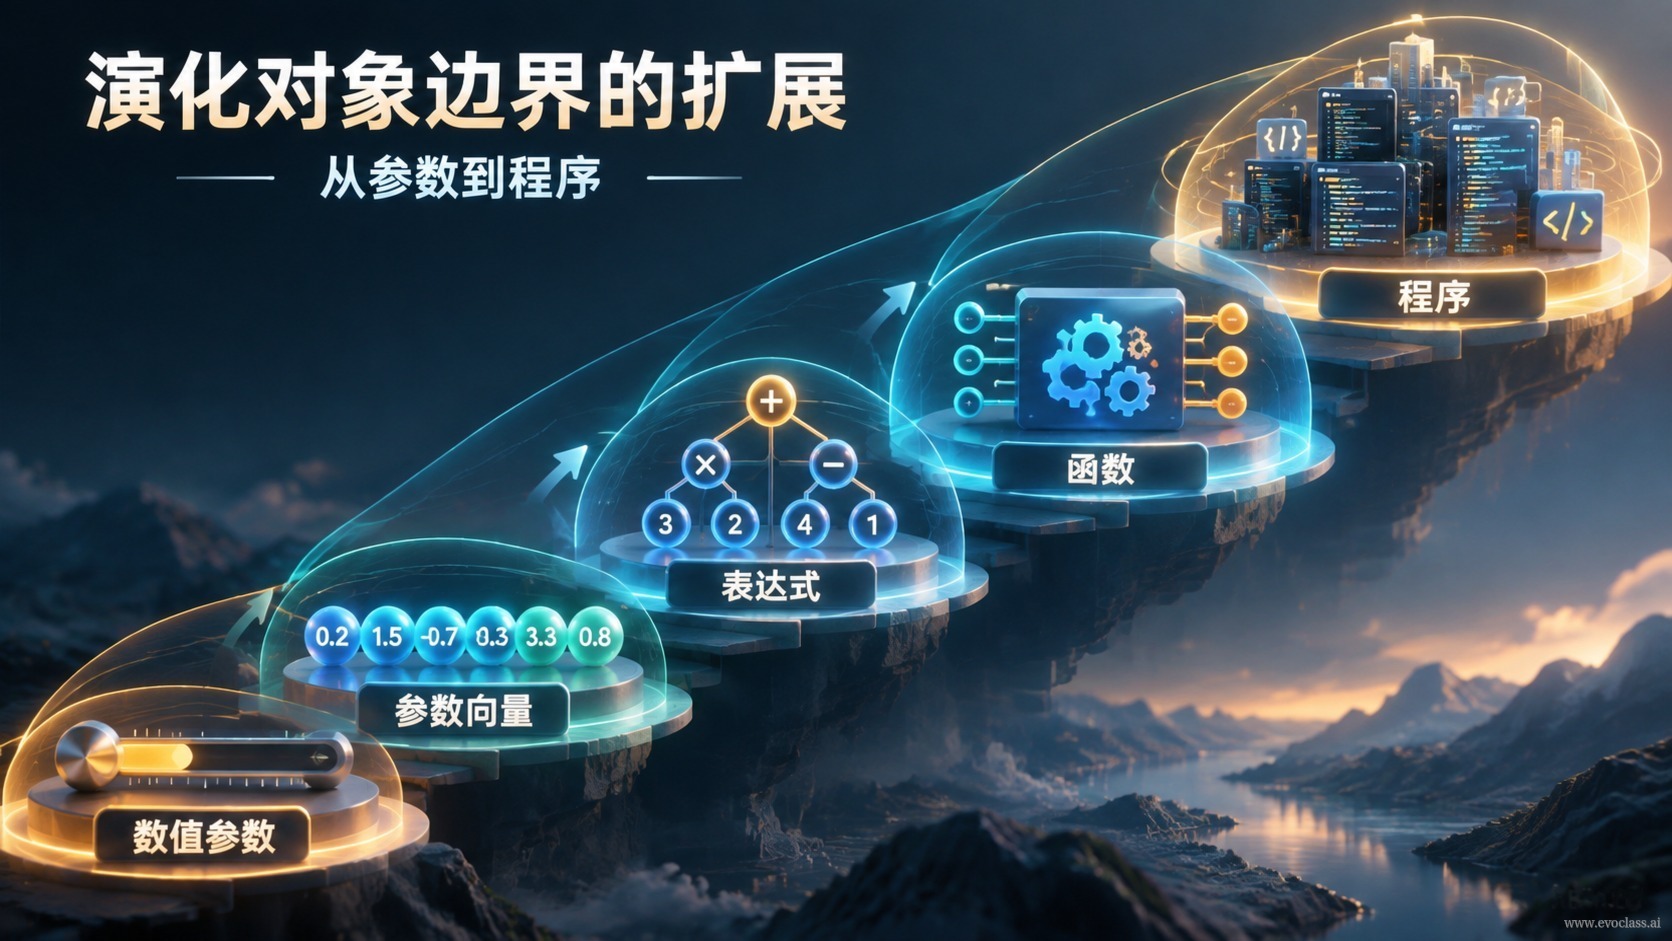
The evolved objectrefers to the part of an evolutionary system that is actually encoded, mutated, evaluated, and selected. Classical evolutionary algorithms assume this object is simply a set of numerical parameters; but on the modern foundation built jointly from GPUs and large models, this boundary is being pushed outward: from numerical parameters, to hyperparameters and model architecture, then to algorithmic mechanisms and operators, and finally to programs and persistent software engineering states.
The key to understanding this ladder is to grasp three things at once: how the objectis represented, what it isconstrained by, and what signalsare used for evaluation. Each time the object moves up a level, all three change together.
- Numerical parameter layer: the object is a continuous real-valued vector θ \in \mathbb{R}^d, such as the learning rate, weights, or the mutation factor in differential evolution. The constraint is mainly the value range, and the evaluation is typically a single scalar objective f(θ).
- Hyperparameter and model architecture layer: the object contains discrete choices, such as the number of layers, width, connectivity, and data augmentation strategy. The search space becomes mixed-type and expands combinatorially at a rapid pace, so evaluation must additionally focus on generalization ability and overfitting.
- Algorithmic mechanism and operator layer: the object itself is the mechanism to be executed, such as the mutation strategy in differential evolution, how inertia coefficients are combined in particle swarm optimization, or the specific form of a loss function. Candidates must satisfy syntactic and semantic constraints, and evaluation shifts from “whose score is higher” to robustness, stability, and multi-objective trade-offs.
- Program and engineering state layer: the object becomes a training script, pipeline configuration, dependency relationships, and project state. A candidate is considered valid only after passing compilation, testing, and acceptance, and evaluation is upgraded to system-level feedback: how much accuracy improves, whether resource overhead is acceptable, and whether results can be reproduced.
Why the boundary expands outward
Two forces drive this together. First, the scale of compute has opened up the possibility of parallel exploration: the serial loops once written around a single candidate have been replaced by tensorization and batch parallelism, allowing an entire population to be generated and evaluated in one pass. Second, large models can understand natural language, code, and domain context, enabling the system to construct structurally complex candidates—encoding and mutation schemes that once had to be designed by hand can now be generated with the model’s participation.
When the “method for generating candidates” can itself be expressed and evaluated, a natural question arises: if candidate solutions can be evolved, can the method that produces them also become an evolved object? This is exactly the step from “optimizing solutions” to “optimizing the algorithm itself.”
Evaluation signals must be upgraded along with the object
At the parameter layer, a single scalar objective is enough to drive the search, such as \min f(θ). At the program layer, no single scalar can capture “whether this code is worth keeping”: evaluation becomes a constrained multi-objective trade-off that must simultaneously consider accuracy f1, evaluation cost f2 , and stability f3, and, under the constraint C(x) ≤ 0 , seek a set of mutually non-dominated candidates. A commonly used engineering checklist includes: does it compile, are tests covered, does the benchmark improve, is resource overhead acceptable, and can results be reproduced.
Common misconception: expansion does not mean generating at will
Pushing the object boundary outward does not mean code can be generated arbitrarily. The more freedom the object has, the more constraints do not disappear—they simply shift from “value range” to “syntax, interfaces, and executability”; the burden of verification is not reduced but increased. Teams that open up script-level evolution typically run into two practical problems first: the search space explodes, and a large number of “runs but yields no gain” candidates eat up the evaluation budget.
A more prudent approach is therefore to open up layer by layer: gradually expand the range allowed to change, first use low-cost screening or surrogate models to rule out obviously invalid candidates, then reserve high-fidelity evaluation for the few promising options, and make the trade-off between accuracy and overhead explicit.
Hierarchy diagram of evolved objects progressing from numerical parameters to complex code structuresStudy the hierarchy diagram showing evolved objects progressing from numerical parameters to complex code structures, and consider how it relates to “the evolved object expanding from parameters to programs, model architectures, algorithmic mechanisms, and software engineering states.”