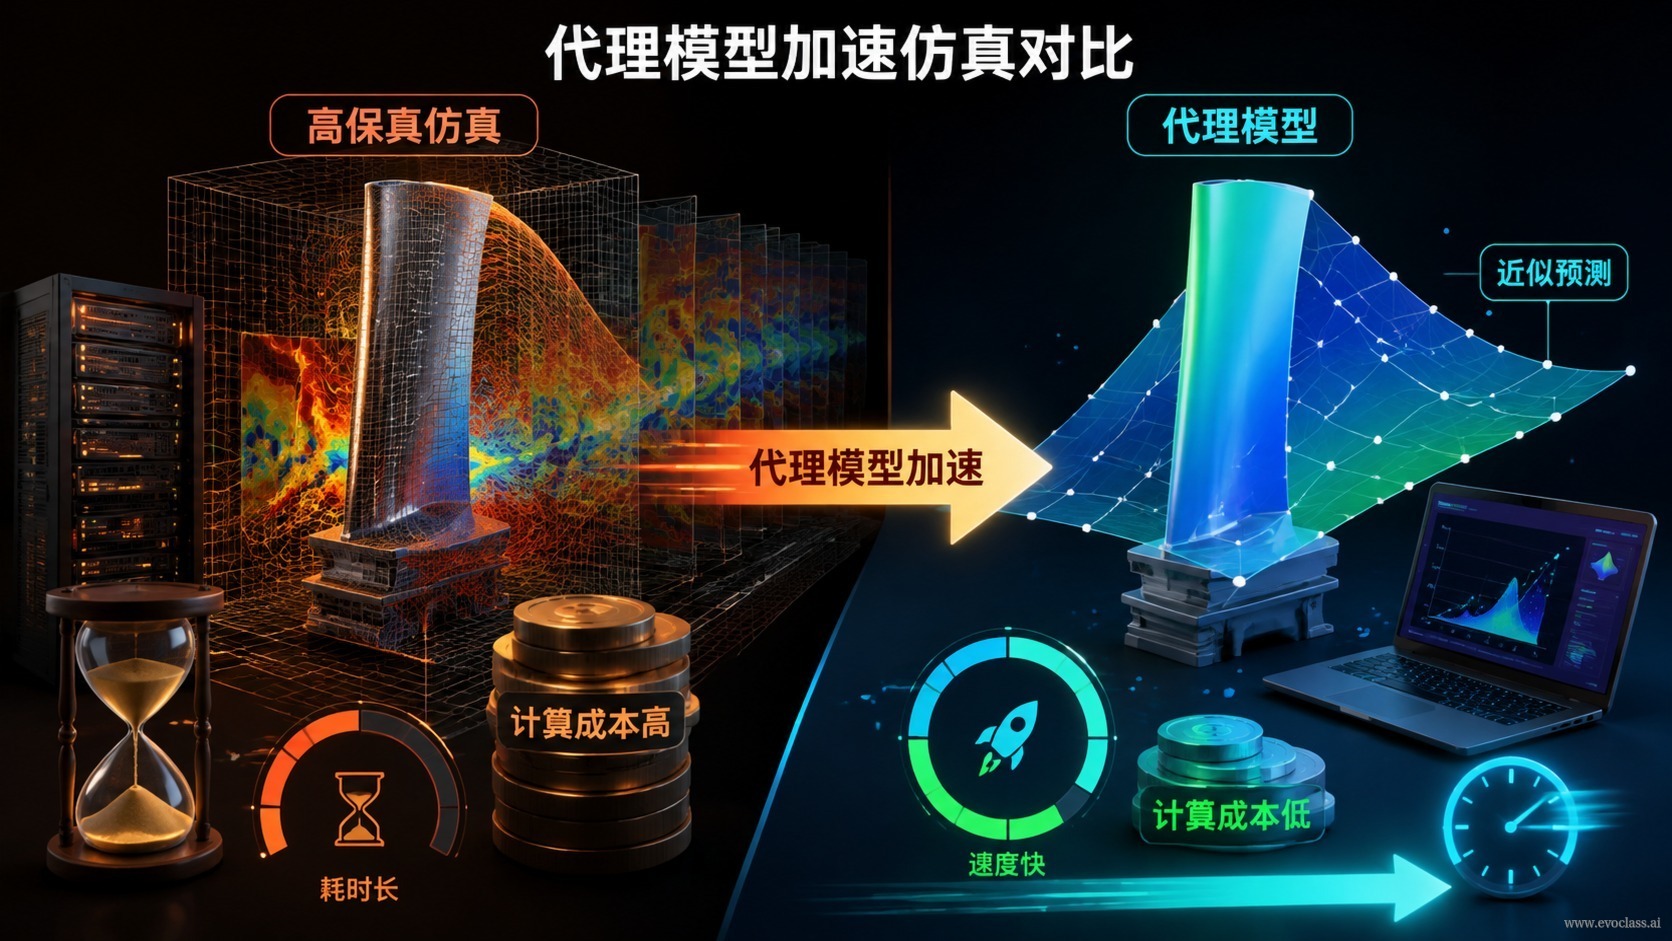
In complex engineering design tasks such as supercritical airfoils,high-fidelity simulation(CFD, finite element analysis) often takes anywhere from tens of minutes to several hours per evaluation. If such simulations are embedded directly into the evolutionary loop, every individual in each generation must be evaluated one by one, quickly draining the computational budget within a few dozen generations and shrinking the explorable search space accordingly.
surrogate models(also called approximation models or metamodels) replace or partially replace high-fidelity simulation with low-cost approximations: they learn an input–output mapping from existing simulation samples and rapidly predict the performance of candidate designs during multi-objective evolutionary optimization, thereby overcoming the bottleneck of expensive high-accuracy simulation.
Why High-Fidelity Simulation Cannot Simply Be Dropped into the Evolutionary Loop
- Source of the bottleneck: For problems such as supercritical airfoils and structural strength, a single CFD / finite element simulation is time-consuming, while evolutionary algorithms must evaluate the entire population in every generation, so the number of evaluations consumes the computational budget in roughly a linear fashion.
- Direct consequence: The budget is consumed within just a few generations, forcing the population size and number of iterations to shrink, making it hard to fully explore the multi-objective front, and effectively locking off the real design space because it is "too expensive to evaluate."
Basic Principles of Surrogate Models
Using baseline airfoils, perturbed samples, and otherexisting datato train a mapping of "candidate design → objective values and constraint performance," it becomes acheap approximate evaluator. In the evolutionary loop, candidates are first scored in batches by the surrogate, and only a few candidates with top scores or large uncertainty are sent to high-fidelity simulation for verification.
Four Steps of the Acceleration Path
- Offline training: Train the surrogate model on initial sampling data to establish a preliminary input–output mapping.
- :: In each generation, predict multiple objective values for all candidates simultaneously, replacing point-by-point high-fidelity simulation.
- Surrogate-assisted selection: Combine predicted values with uncertainty to select candidates with high potential or high information content.
- Backfill correction: Write a small number of high-fidelity results back into the sample library and incrementally update the surrogate so that subsequent predictions stay close to the true response surface.
Trade-off Between Accuracy and Cost
The more complex the surrogate model (from simple regression to Gaussian processes and deep networks), the more accurate it usually is—but the training and inference overhead also rises. The key constraint is thatthe surrogate must be significantly faster than the high-fidelity simulation, otherwise it becomes the new bottleneck; at the same time, its accuracy must be sufficient to support selection pressure, otherwise evolution will be steered in the wrong direction.
Limits and Risks
A surrogate is only reliable near its training distribution. When the search pushes candidates into out-of-distribution regions, predictions may produce plausible-looking but badly off values that mislead the search direction. Practical countermeasures include: outputting uncertainty estimates, setting confidence thresholds for screening, forcing out-of-bounds candidates through high-fidelity validation, and periodically checking surrogate quality with actual error statistics.
Surrogate Model Acceleration ComparisonThe figure compares the evaluation workflow of high-fidelity simulation versus surrogate models in evolutionary optimization: the former is time-consuming per point and cannot sustain large-population, multi-generation search, while the latter learns a mapping from candidate designs to objective values using existing samples and performs fast batch predictions. Only top-ranked or high-uncertainty candidates are sent for high-fidelity verification, and the results are backfilled to update the surrogate, concentrating the scarce simulation budget on the key candidates.