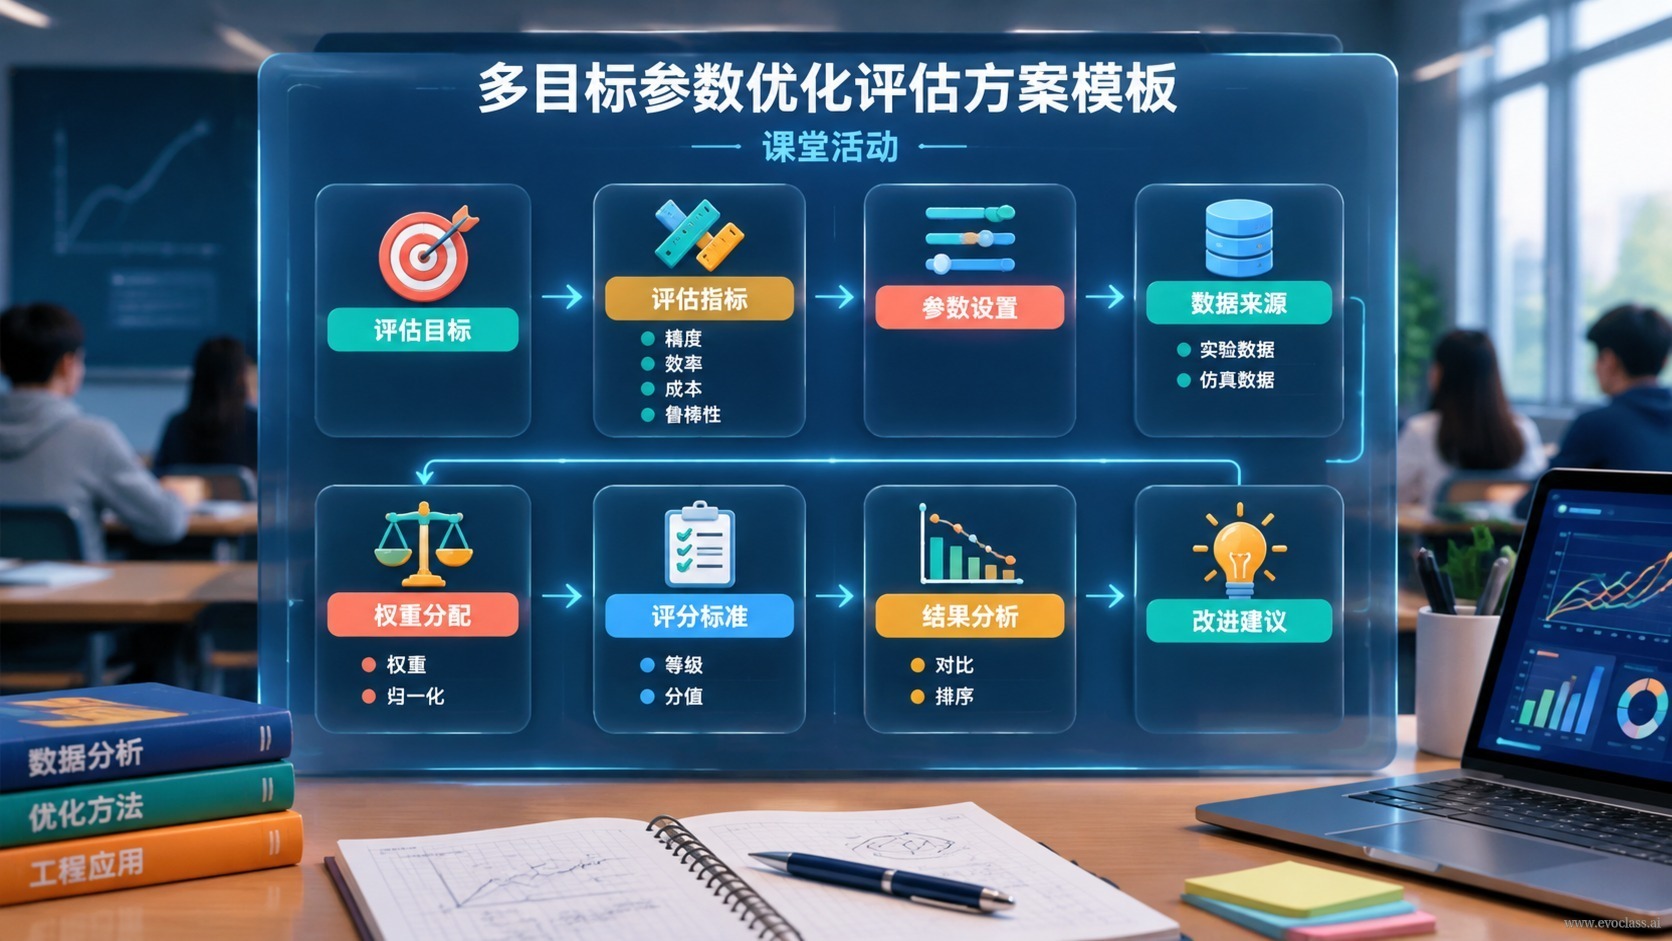
This page is aclass activity design: it turns thelift–dragpair of conflicting objectives into a reproducible, comparable multi-objective parameter optimization evaluation plan deliverable to expert decision-making. The point is not to have the model give a direct answer, but to design an evaluation mechanism that can be repeatedly tested — who takes part in the evaluation, which metrics are used, under what constraints and budget, and by what rules candidates are retained.
The activity simulates a closed loop:generate candidates → enter evaluation → compare benefits, costs, and constraints based on feedback → retain effective solutions → record and proceed to the next round. You need to propose a plan for a parameterized object (for example, airfoil parameters) and make the lift–drag trade-off explicitly visible in it — in a word, turn "conflict" into "executable review rules."
Metrics, Constraints, and Budget
- Lift objectivedefined as maximizing the lift coefficient or lift performance;drag objectivedefined as minimizing the drag coefficient or drag performance. These two are the original conflicting objectives and must each be listed independently.
- Composite metrics: metrics such as the lift-to-drag ratio can be used for explanation and presentation, but they cannot replace the original conflicting objectives — otherwise the trade-off would be prematurely "flattened" by a single ratio.
- Constraint tiering: parameter bounds and geometric and engineering constraints (such as relative thickness and pitching moment range) are usually set as hard constraints, and any violation leads to elimination; performance preferences and cost preferences are set as soft preferences for ranking.
- Budget declaration: specify the number of simulation or surrogate model calls, time, and compute limits, and distinguish the quota for "surrogate evaluation" and "high-fidelity verification"; otherwise different plans cannot be compared fairly.
Evaluation Process and Candidate Generation
The evaluation closed loop is organized into six steps:parameter representation → candidate generation → evaluation computation → metric aggregation → solution comparison → record archiving. The candidate generation rules determine the coverage of the exploration: initial sampling spreads out globally, perturbation, crossover, and mutation handle local refinement, and preference guidance intensifies coverage in regions experts care about. Candidates are required to be distributed across different lift-drag trade-off regions, avoiding collapse of an entire generation into a single direction of "high lift" or "low drag."
Selection Rules and Output Candidate Set
Selection may use Pareto non-dominance, weighted sum, threshold filtering, reference points, or preference ranking. Whichever is chosen, the result should not be "keeping only the one with the highest total score": the output should be a set of candidates covering different trade-offs, accompanied by metric evidence, constraint satisfaction, differences among candidates, and uncertainty ranges, so that domain experts can judge whether the trade-offs are reasonable.
Deliverables
A one-page evaluation plan template: metrics table (including original objectives and auxiliary metrics), flowchart (six-step closed loop), candidate generation rules, selection rules, output candidate set, and risk and uncertainty notes. Also record parameters, metric definitions, evaluation budget, random seeds, selection criteria, and elimination rationale, so that the next round of exploration can inherit them directly.
Class Activity Evaluation Plan TemplateThe figure is a one-page evaluation plan template for the class activity: centered on the two independent conflicting objectives of lift and drag, it lists the metrics table, six-step evaluation closed loop, candidate generation rules, selection rules, and output candidate set. It also requires declaring the evaluation budget and recording random seeds and elimination rationale, making the plan comparable, reproducible, and ready for expert decision-making.