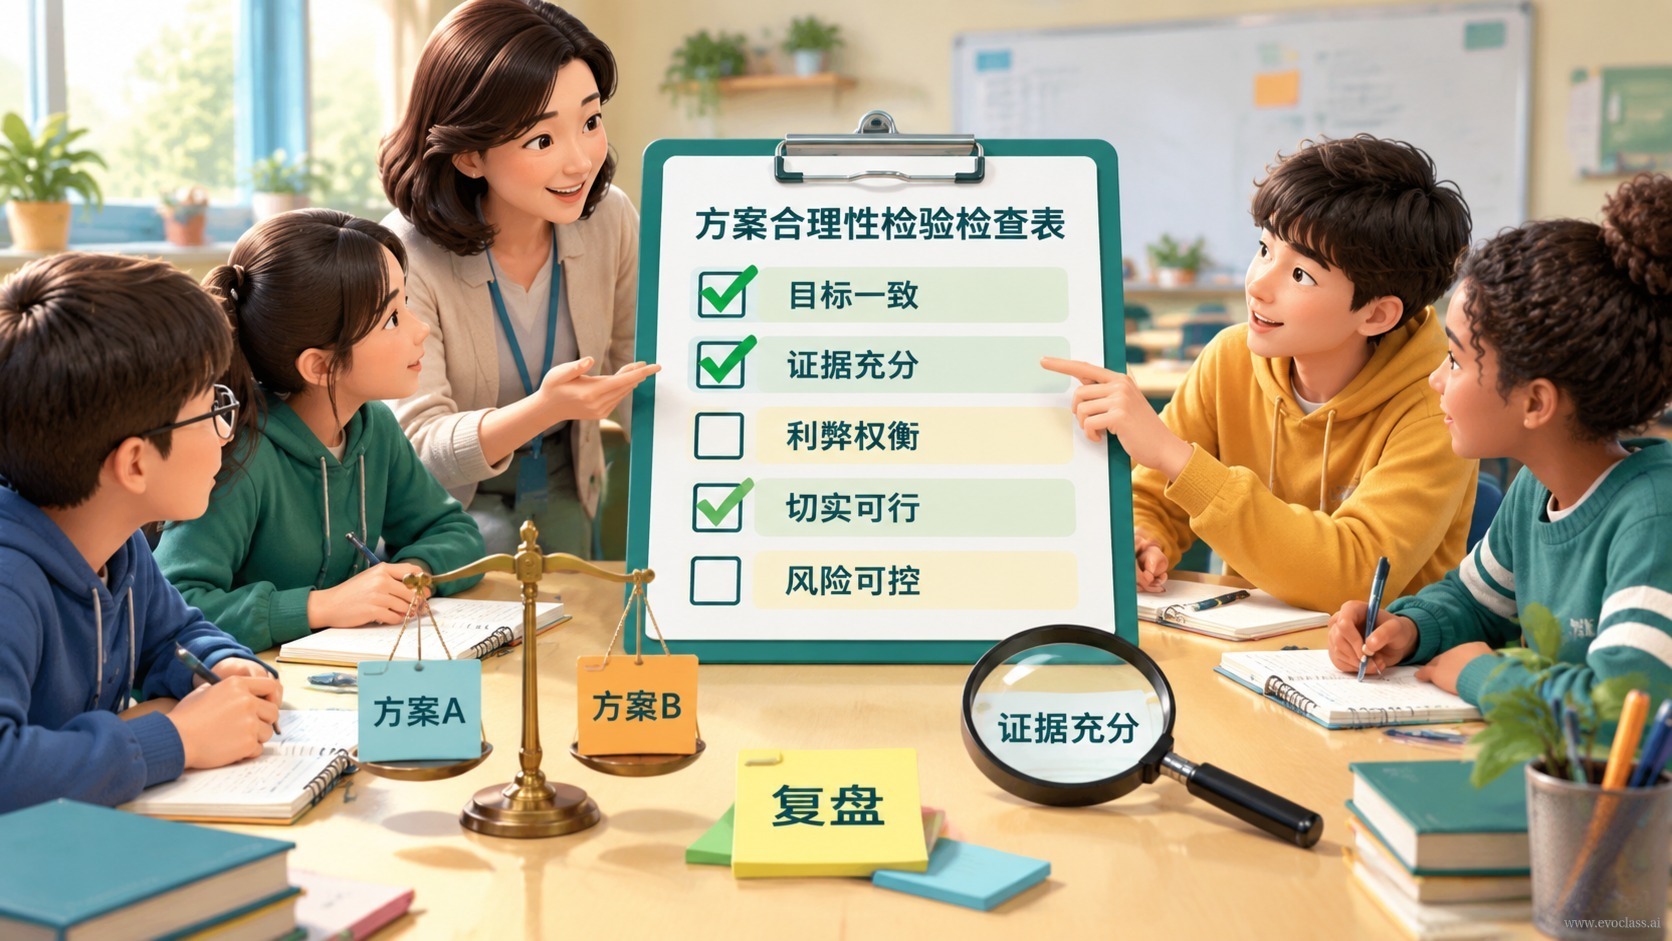
This page debriefs the results of the class activity “Designing a Multi-Objective Parameter Optimization Evaluation Plan.” There is only one core question:Is this trade-off plan sound— Can it identify overlooked key metrics and the conflicts between objectives, and use them to clarify the direction for adjusting parameter configurations, so that the plan genuinely meets real-world engineering decision needs?
1. Conduct a coverage check against real-world engineering decisions
A debrief is not about rerunning the experiment—it is about putting the evaluation plan back into a real decision scenario to verify it: if domain experts were to make the call, are the objectives, constraints, and preferences provided by the plan sufficient to support that decision? So the first step is acoverage check— prioritize uncovering overlooked key metrics rather than rushing to compare whose final score is higher.
- Objective coverage: whether all quantities that decision-makers truly care about are included in the objective set—for example, performance, cost, reliability, and manufacturability.
- Constraints and preferences: whether hard limits such as geometry, processes, and safety margins are explicitly written as constraints; whether preferences are explicitly expressed as weights or reference points rather than left as subjective impressions.
- The cost of omission: when the objective set is incomplete, optimization merely continues refining a flawed model—the more “beautiful” the result, the further it drifts from real needs.
2. Explicitly identify conflicts and redundancies
A debrief must distinguish two relationship types that look similar but require opposite handling:Conflictmeans two metrics trade off against each other, and they should be retained as multiple objectives so the trade-off relationship is explicitly shown on the frontier;Redundancymeans two metrics change in the same direction with highly overlapping information, which double-weights the same requirement—one should be merged or removed. Also check whether any constraint has been mistaken for an objective, or any objective has been mistakenly written as a weight.
3. Does the parameter configuration match the problem structure?
The configuration of multi-objective parameter optimization must match the problem scale, evaluation cost, and decision needs. During the debrief, check item by item: is the population size and number of candidate solutions sufficient to cover the trade-off range; does the iteration budget match the surrogate model's accuracy; do operator parameters such as mutation, crossover, and selection pressure keep exploration and exploitation balanced; does the sampling strategy direct the limited simulation budget toward high-information regions? Any mismatch will manifest as “results exist, but they are unusable.”
4. Derive adjustment directions from debrief findings
- Insufficient diversity(candidates clustered, distribution crowded): increase the population size or candidate output sets.
- Premature convergence(exploration lost early): adjust mutation strength and selection pressure, and relax elitism.
- Evaluation cost too high: improve surrogate model accuracy and optimize infill and sampling strategies, rather than reducing the exploration scale.
- Preference drift: adjust weights or shift reference points so the selected solutions fall in the region decision-makers truly care about.
- Missed metrics or conflicts: add the missing metrics and retain trade-off relationships as a multi-objective structure, rather than compressing them into a single objective or checking them after the fact.
5. Criteria for judging soundness
A qualified evaluation plan doesn't stop at “being able to produce results”—it must also satisfy three conditions:Comparable— domain experts can clearly see the trade-offs among candidates;Actionable— a plan can be selected from the frontier based on preferences;Reproducible— parameters, random seeds, and workflow records are complete. The final output should be diverse candidates that balance all metrics, not a solitary “optimal solution.”
Plan Soundness Review ChecklistThe diagram shows a checklist for assessing the soundness of a trade-off plan: first perform a coverage check to confirm that key metrics, hard constraints, and preferences are not overlooked; then identify which conflicts should be retained as multiple objectives and which redundancies should be merged. Next, verify population size, evaluation budget, operator parameters, and sampling strategy, and derive adjustment directions from diversity, convergence, cost, and preference drift.