In evolutionary computation,diversityis a prerequisite for the algorithm to work: only by maintaining enough candidate solutions will selection pressure avoid prematurely squeezing the population into a local optimum. But diversity also means a huge computational load—a single run often requires evaluating tens of thousands, even millions, of candidate solutions. When candidates are written as ordinary arrays of objects and fed one by one into evaluation through item-by-item loops, most of the computation time is spent on item-by-item scheduling and host-language control flow rather than on actual numerical operations. This is preciselythe root cause of why traditional serial CPU loops are inefficient when handling tens of thousands of candidate evaluations.
A Leap in Representation: From Candidate Lists to Tensorized Computation Graphs
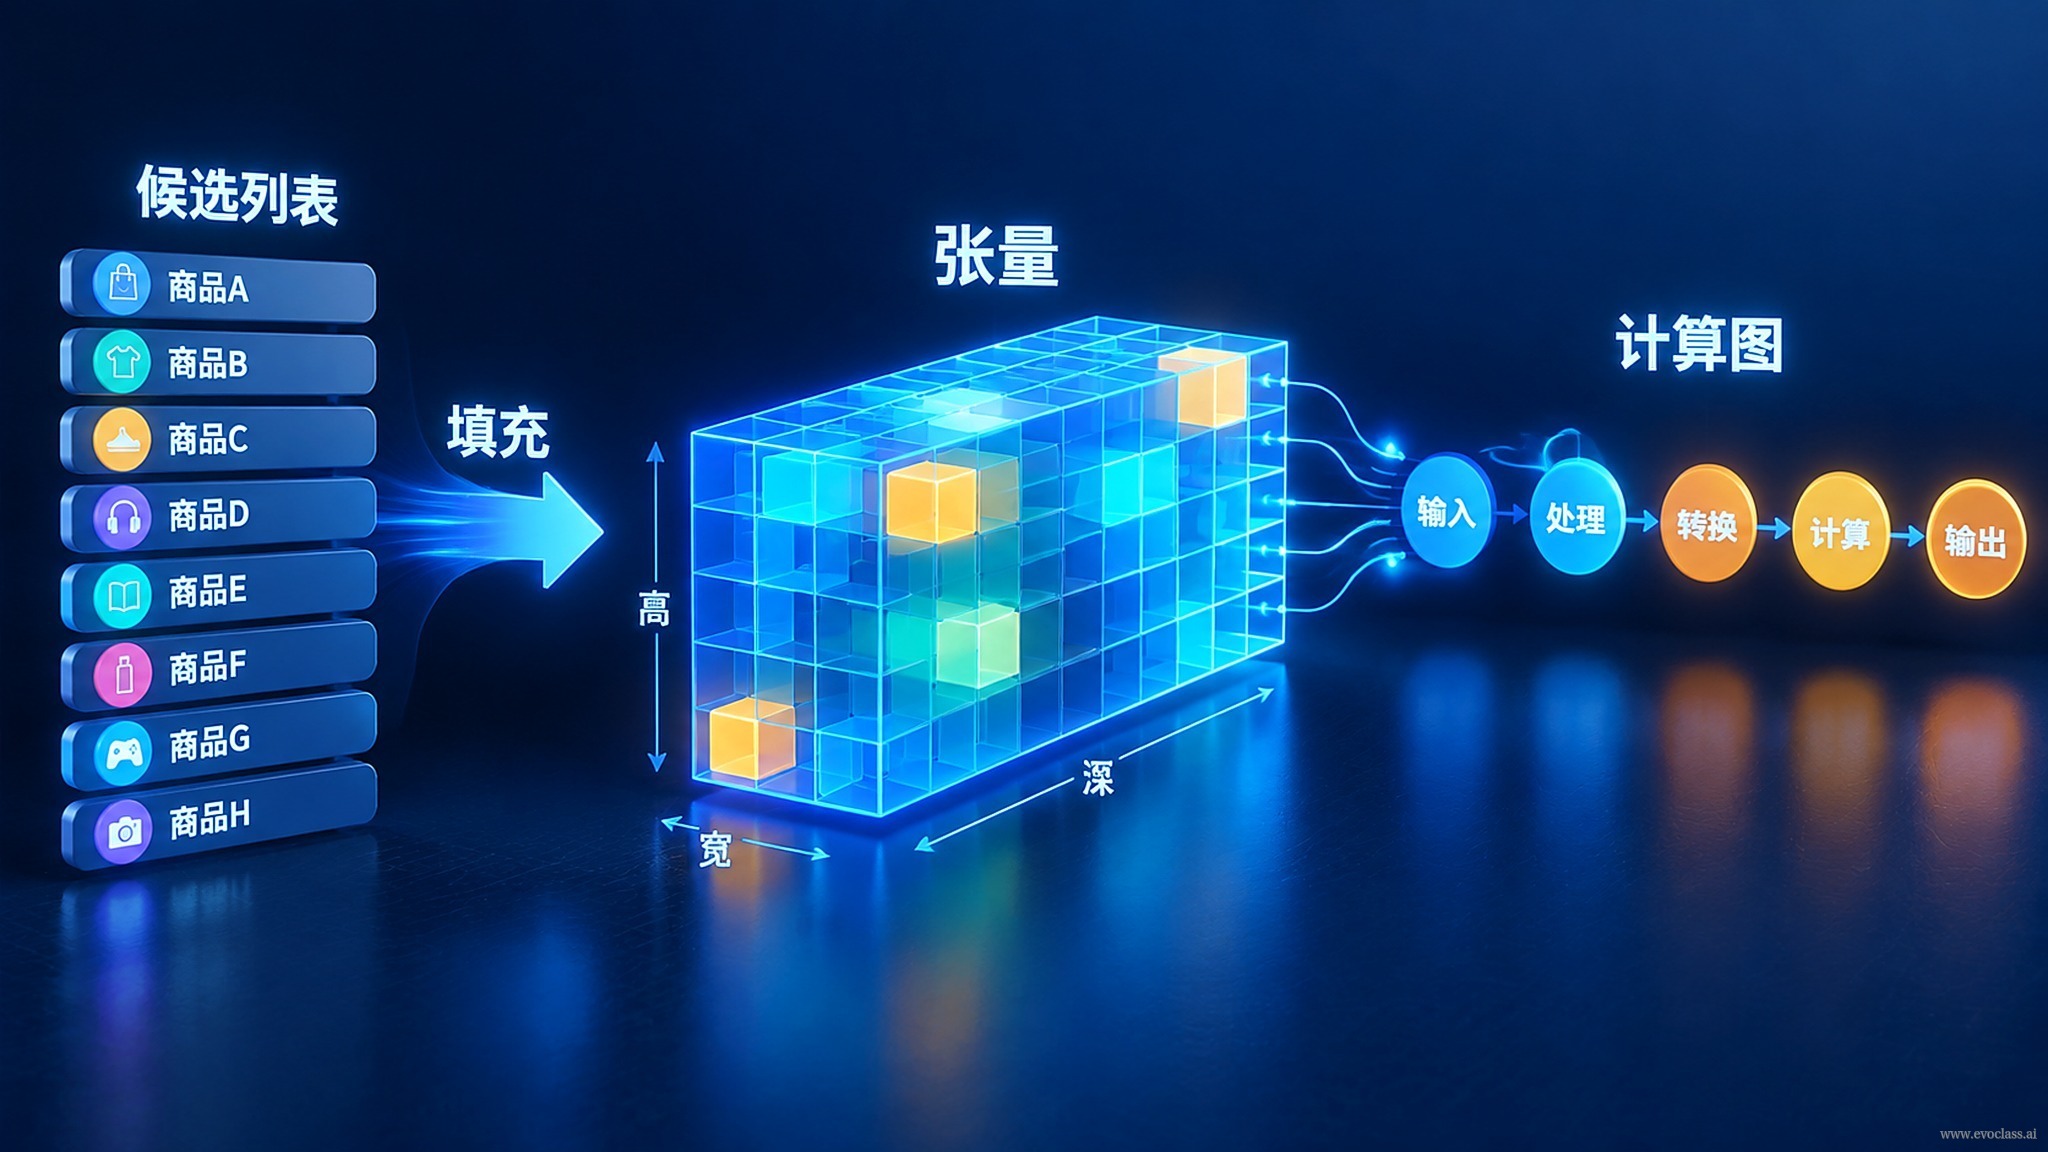
What EvoX brings is not a local speedup of some operator, buta change in how the evolutionary process is represented: a shift from list-style processing of candidates one by one to batch computation with tensors as first-class citizens. The set of candidates is no longer scattered across arrays of objects; instead, together with evaluation results and algorithm state, it is uniformly organized into tensors so that everything can participate in computation as a whole.
- Candidate tensor: The entire generation of candidates is written as a tensor of shape [population size, solution dimension]. A "candidate" is now just a row in the tensor rather than a separate host-language object.
- Batch operators: Operations such as mutation act directly on the entire population; a single call updates all candidates instead of looping N times.
- Batch evaluation: Using evaluate(candidate tensor) to obtain the evaluation results for the whole generation in one go, the unit of evaluation changes from "one" to "a batch".
- Computation graph: Selection and state updates are no longer merely serial control logic but nodes in the graph, thus gaining compiler optimization opportunities such as operator fusion and parallel scheduling.
Comparing the Two Styles
The list-style approach is roughly: take out candidates one by one, evaluate one by one, compare one by one, and update state—every step relies on host-language loops and is hard to optimize as a whole. The tensorized approach is: candidate tensor → mutation → evaluation → selection → state update, with the entire chain composed of tensor operations and expressed as a single computation graph that the compiler can fuse and schedule across devices. Note that the algorithm's logic (mutation distribution, selection pressure) is not rewritten; what is rewritten isthe representation.
Structural Conversion from Candidate Lists to TensorsList-style processing treats each candidate as a separate object evaluated one by one in a loop, whereas tensorization writes the entire generation of candidates as a tensor of shape [population size, solution dimension], where a candidate is merely one row; mutation, evaluation, and selection are then invoked in batches and organized into a compilable, optimizable computation graph—without changing the algorithm's logic itself.