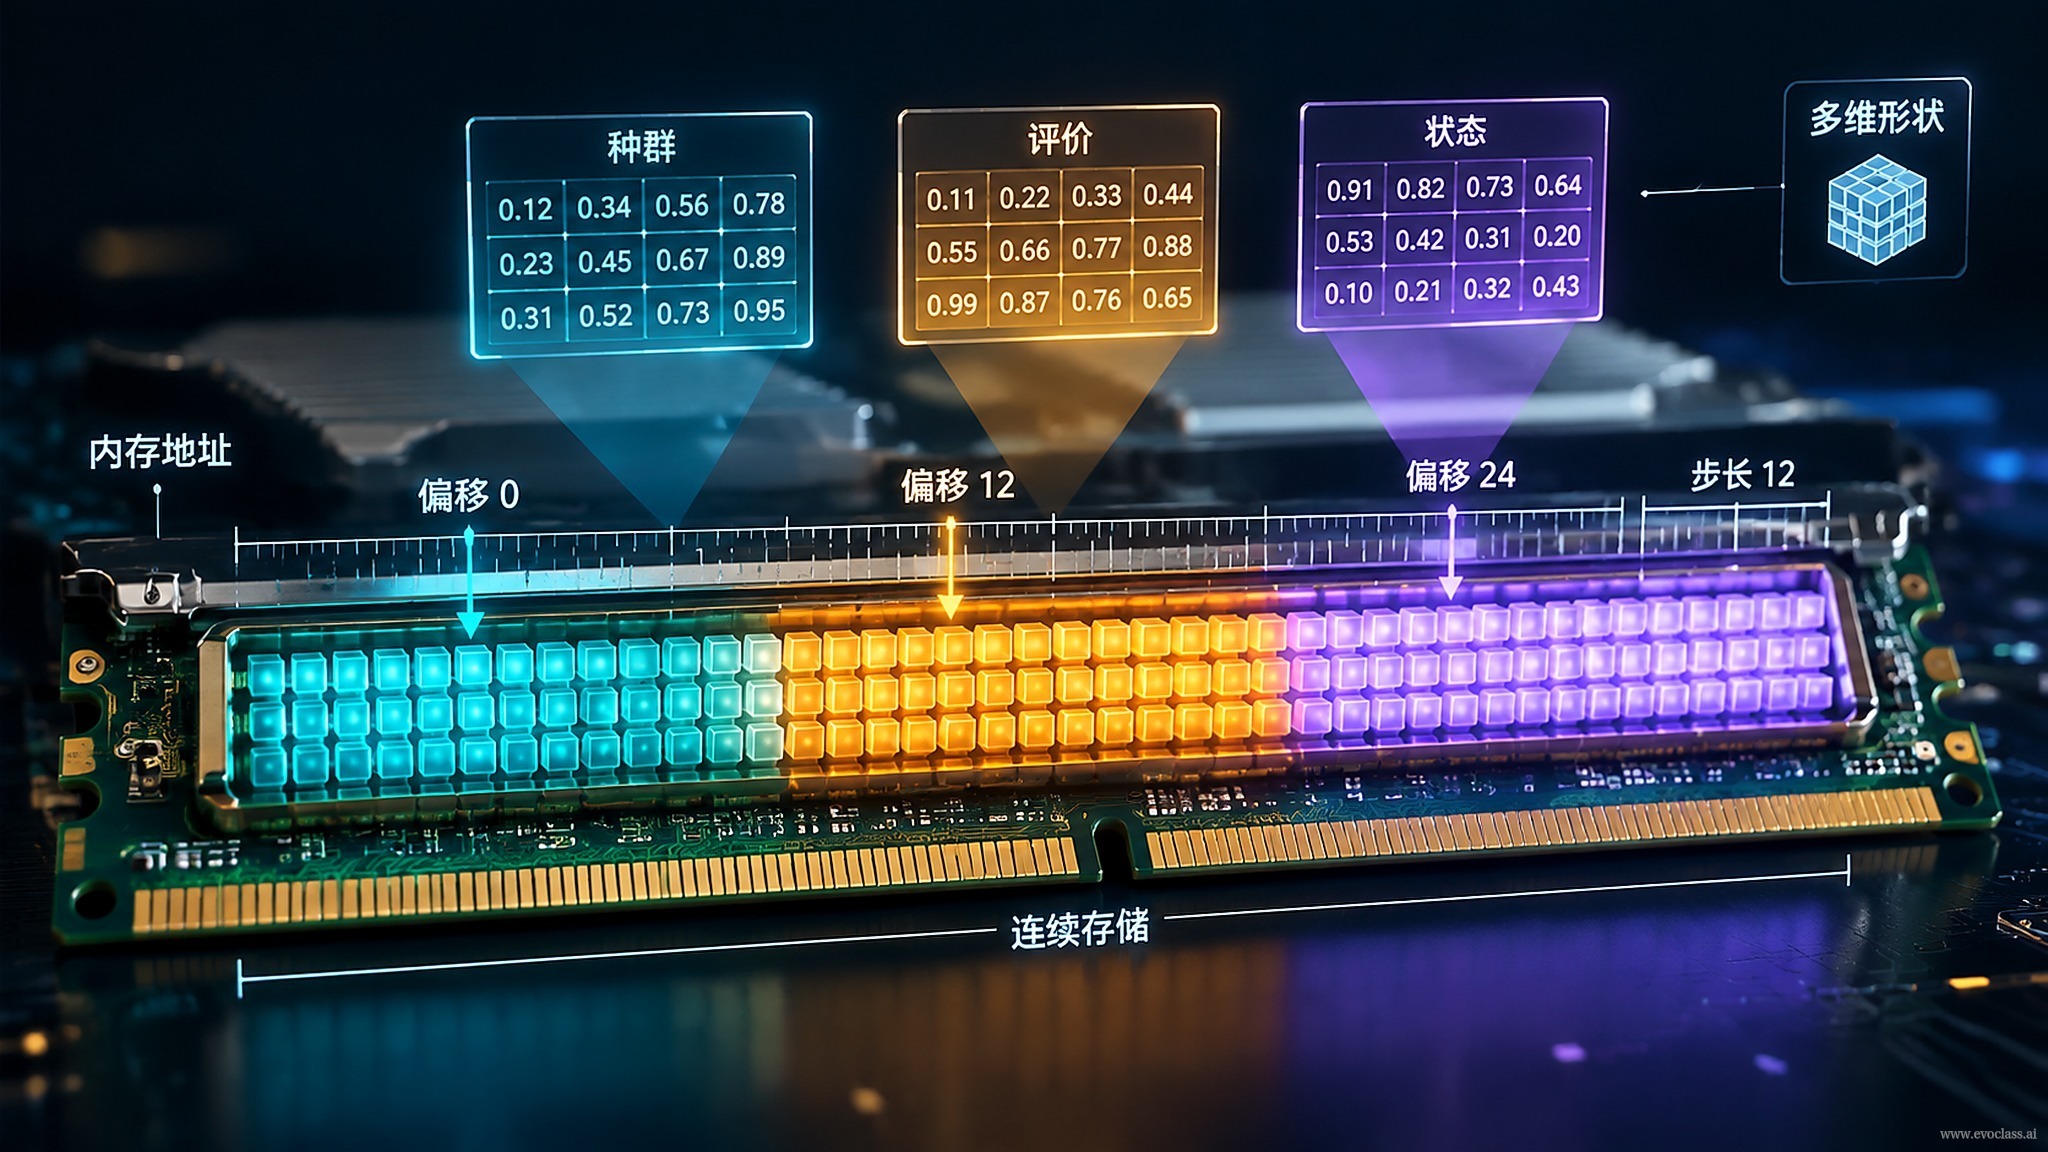
In the engineering implementation of evolutionary algorithms,tensorized organizationmaps the questions of “what the population is, how it is evaluated, and how far it has progressed” from scattered objects and lists into uniform, regular tensors. At its core, it establishes a unified data contract for the population, evaluation, and state, giving batched computation, device residency, and subsequent parallel scheduling a shared memory semantics.
Population Tensorization: Encoded as [N, D]
Organize N candidate solutions along the batch dimension into an encoding tensor of shape [N, D]. Continuous variables, discrete variables, or multi-segment encodings can be expressed as field tensors or grouped blocks while maintaining a uniform data type and device placement.
- Batch dimension outermost: N is typically placed as the outermost dimension so that the same operator executes in a vectorized manner over the entire batch.
- Field blocking: If an individual consists of multiple parameter segments, it can be split into [N, D1] + [N, D2] + … while keeping contiguous storage.
- Variable-length handling: Variable-length individuals are handled with padding plus masking or bucketing to prevent heterogeneous structures from breaking batched computation.
Matrix Representation of Evaluation Results: [N, M] and [N, K]
A single batched evaluation produces an [N, M] fitness matrix; multiple objectives, multiple constraints, and additional metrics can be placed side by side as [N, M+K] or stored in separate tables, avoiding per-individual loops that call the evaluation function.
Unified Management of State Tensors
Generation number, RNG state, strategy hyperparameters, best solution, history cache, ranking or sampling state, and more also go into tensors or a structured state container, ensuring reproducibility, traceability, and batch updates.
Benefits and Boundaries of the Organization
Unified tensors reduce host–device round trips, lower loop overhead, and provide a data foundation for subsequent operator parallelism; however, they require handling mask validity, padding waste, multi-objective scaling growth, and state synchronization costs.
Tensor Layout of Population, Evaluation, and StateThe population is encoded as an [N, D] tensor, and a single batched evaluation yields an [N, M] fitness matrix; multiple objectives or constraints can be extended to [N, M+K]; generation number, best solution, RNG state, and more also reside uniformly on the device as tensors, so that each generation's update is completed as a whole over the same batch dimension, reducing host–device round trips and per-individual loop overhead.