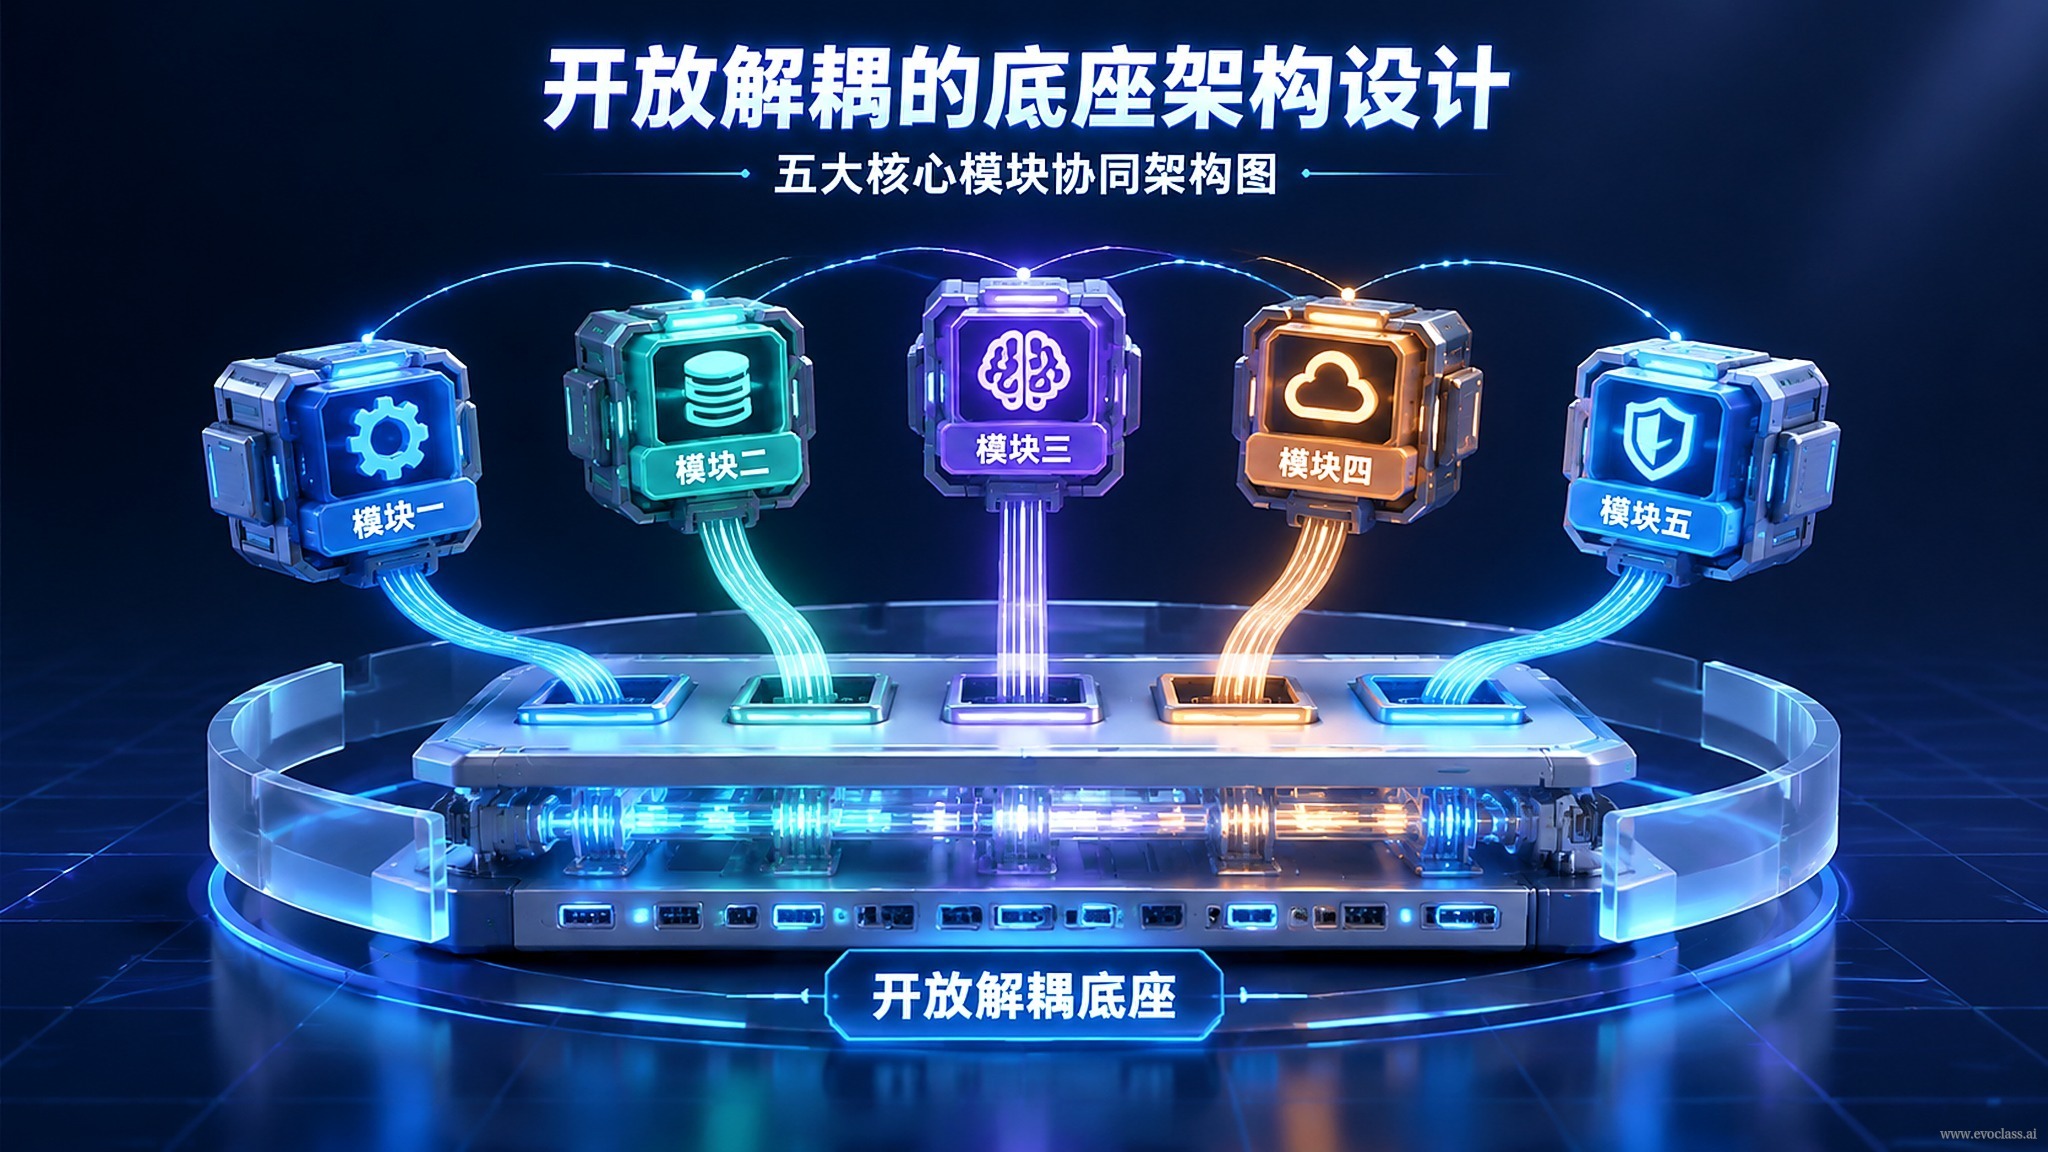
EvoX's core premise is that researchers should not spend their time on parallel communication, device allocation, and distributed fault tolerance. The system is therefore split into five top-level modules—Algorithm,Problem,Workflow,Monitorand the Runtime Scheduler. The first four answer "what to evolve, how to evolve, how to organize, and how to observe," while the Runtime Scheduler answers "where to compute and how to make it run." Once this boundary is drawn, researchers only need to focus on "how to evolve," while the underlying system handles scheduling computation onto GPUs, accelerators, or distributed clusters.
Responsibility Boundaries of the Five Modules
- Algorithm: Describes only the search and update logic (selection, crossover, mutation, update rules). It is not bound to any specific problem and is not aware of which card the tensors reside on.
- Problem: Provides a unified evaluation interface externally, packaging business-side simulations, objective functions, or environments into a form the foundation can call directly.
- Workflow: Organizes the evolution process by stage (initialization, iterative evolution, convergence determination, etc.), deciding "what to do first and what to do next."
- Monitor: Collects metrics at each stage and records population states and convergence curves for analysis and debugging.
- Runtime Scheduler: As the unified execution layer, it abstracts away heterogeneous compute differences, distributes batched computation to GPUs, accelerators, or distributed clusters, and takes over parallelism and communication details.
Portability Benefits of Decoupling
This "high cohesion, low coupling" interface collaboration keeps algorithms and problems independent of each other, and problems independent of compute. When a researcher implements a new mutation operator, they only need to complete the evolution logic within the algorithm module; the problem module continues to provide the unified evaluation interface, the workflow and monitor modules keep their original organization, and the Runtime Scheduler automatically distributes batched tensor computation to GPUs or distributed clusters—no modifications to the underlying execution code are needed.
Because the interfaces are stable, this foundation can support multiple evolutionary scenarios simultaneously—reinforcement learning, genetic programming, combinatorial optimization, and more—avoiding the need to repeatedly build parallel, scheduling, and distributed execution infrastructure for each domain. It's important to distinguish that decoupling reduces "duplicate engineering," not "computing power": whether the layering is truly efficient still requires benchmark experiments to verify that scheduling overhead is acceptable.
EvoX Five Core Modules Collaborative Architecture DiagramThe EvoX foundation consists of five top-level modules: Algorithm, Problem, Workflow, Monitor, and Runtime Scheduler. The first four answer what to evolve, how to evolve, how to organize, and how to observe, while the scheduler is responsible for distributing batched computation to GPUs, accelerators, or distributed clusters. Once this boundary is drawn, researchers only need to focus on evolution logic, while parallel communication, device allocation, and distributed fault tolerance are handled uniformly by the underlying system.