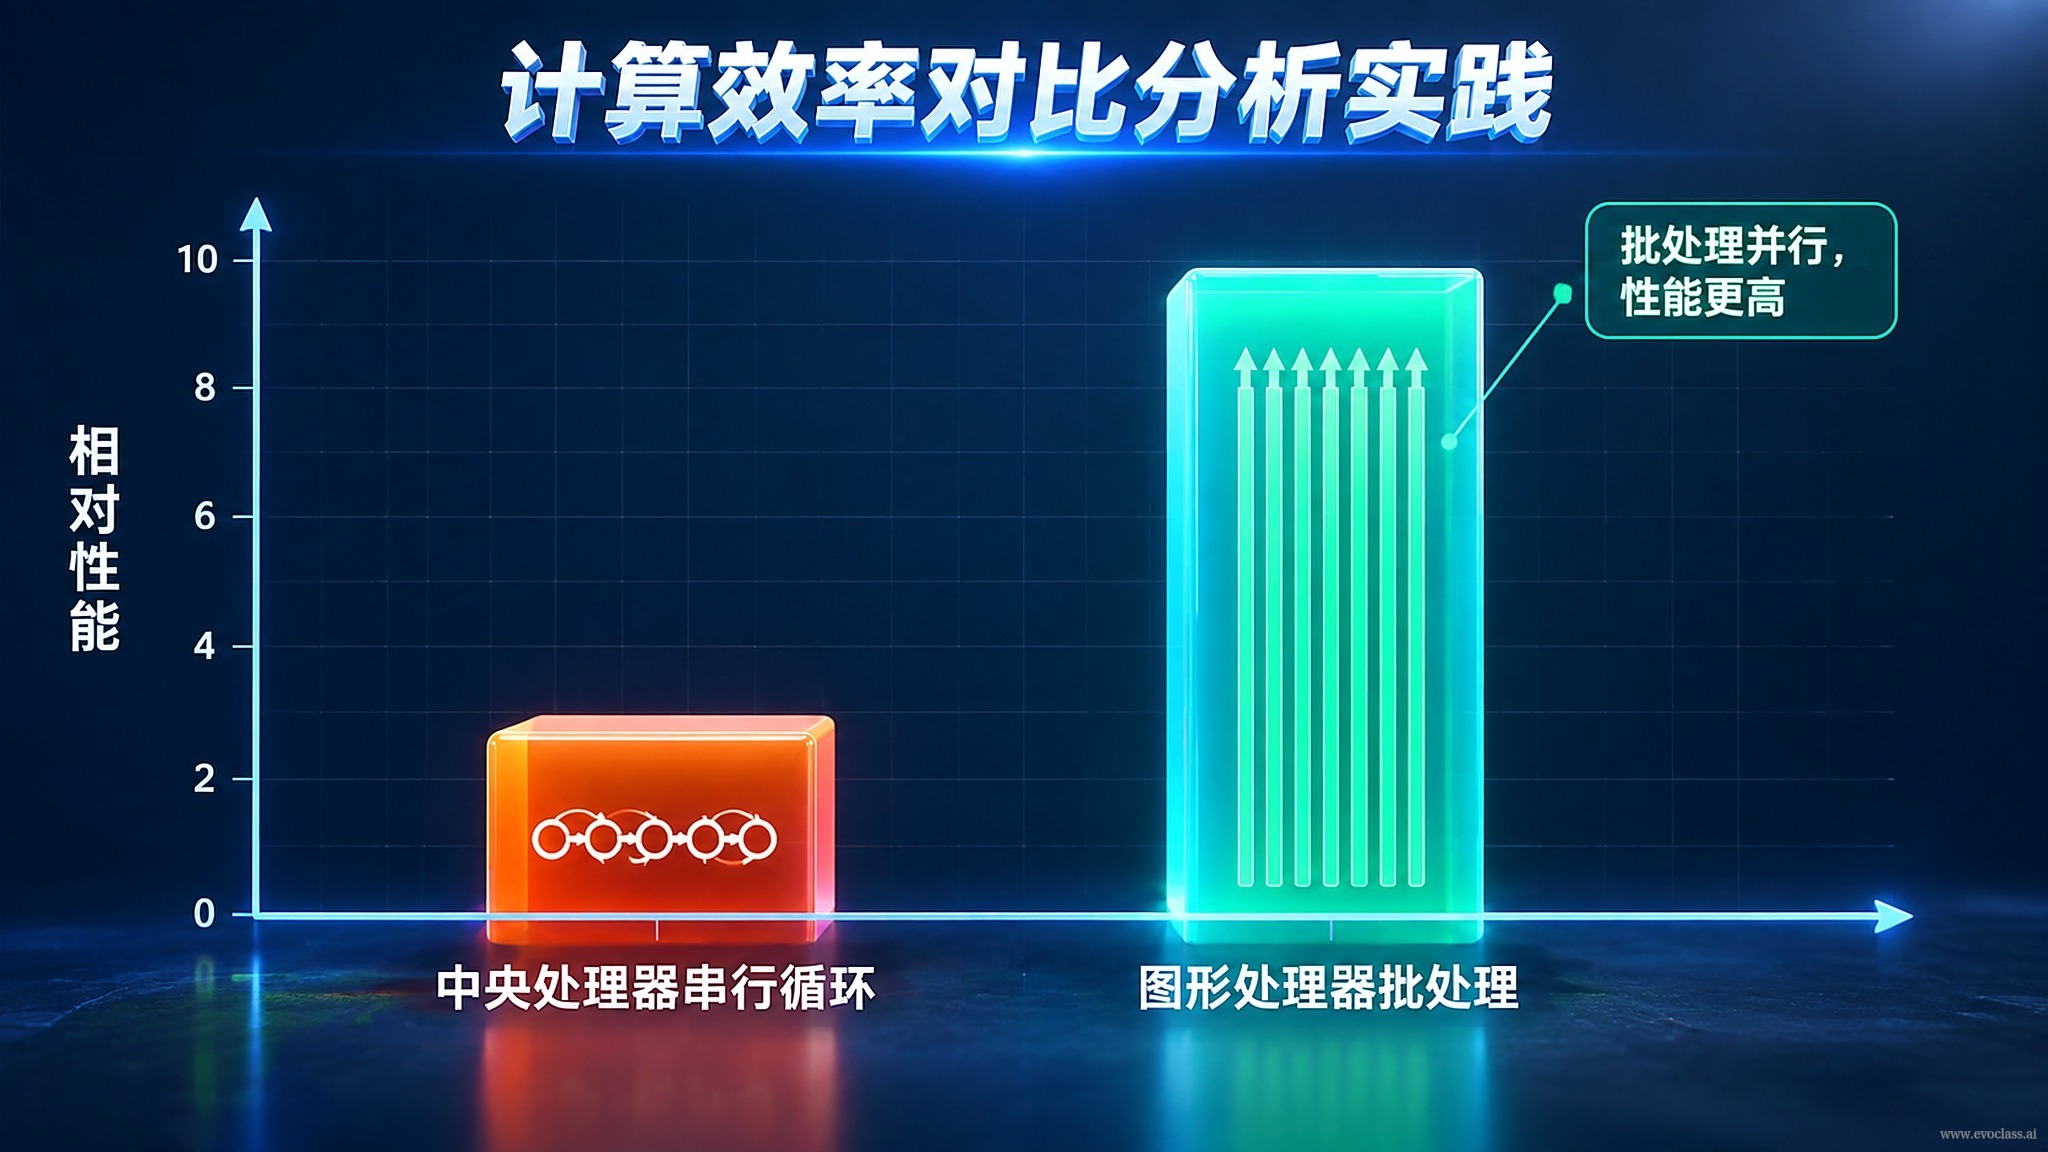
This page grounds the "computational efficiency comparison" in a reproducible hands-on exercise:compare the end-to-end efficiency of traditional CPU serial individual iteration versus EvoX GPU tensor batching on the same evolutionary task. The goal is not to memorize the conclusion that "GPUs are faster," but to understand where the speedup from tensorized parallelism actually comes from, what its costs are, and where its limits lie.
Two Baselines, One Task
- CPU Serial Baseline: each individual calls the evaluation function in a loop, so every generation requires N separate scheduling, state update, and result aggregation steps. Loop control, interpreter overhead, and scattered memory access dilute effective compute, and the more individuals there are, the higher the share of these "non-computational" costs becomes.
- GPU Tensor Reference Implementation: EvoX organizes the population, evaluation inputs, and runtime state as tensors, executing evaluations and operators in batches on the GPU, with a single call covering the entire candidate set—greatly reducing serial loops and scheduling overhead.
Measurement Protocol: Making the Comparison Reproducible
A reproducible comparison mustfix the problem, population size, number of generations, and random seed, then record: per-generation wall-clock time, total elapsed time, throughput (evaluations/sec), speedup, plus GPU utilization and memory usage. Before timing, you need towarm upto rule out the effects of first-time compilation and memory allocation, and performdevice synchronizationat the timing points, while tracking compute time and host–device data transfer time separately. Miss any of these steps, and the resulting speedup may be distorted.
Where the Difference Comes From, and What Constrains It
- Source of benefits: batch parallelism, tensorized operators, and on-device parallelism let a single call process the entire candidate set, completing more evaluations per unit time.
- Constraints: batch size, problem dimensionality, how vectorizable the evaluation function is, host–device copy overhead, and kernel launch overhead all affect the final speedup. A batch that is too small lets launch overhead eat into the gains; if the evaluation function cannot be vectorized, batching has almost nothing to work with.
Practical Takeaways
The right order is:first verify whether the evaluation function can be batched, then compare CPU and GPU implementations. Ultimately, the efficiency advantage should translate into "more generations or more candidate solutions within the same compute budget" and inform deployment choices and experimental design—rather than simply chasing a pretty speedup number.
CPU Serial vs. GPU Batching Efficiency ComparisonIn this comparison, the CPU serial baseline evaluates individuals one by one in a loop, requiring N scheduling and state updates per generation, with interpreter and memory access overhead diluting effective compute; GPU batching organizes the population and evaluation inputs as tensors, with a single call covering the entire candidate set. The speedup is constrained by batch size, how vectorizable the evaluation function is, and host–device copy overhead.