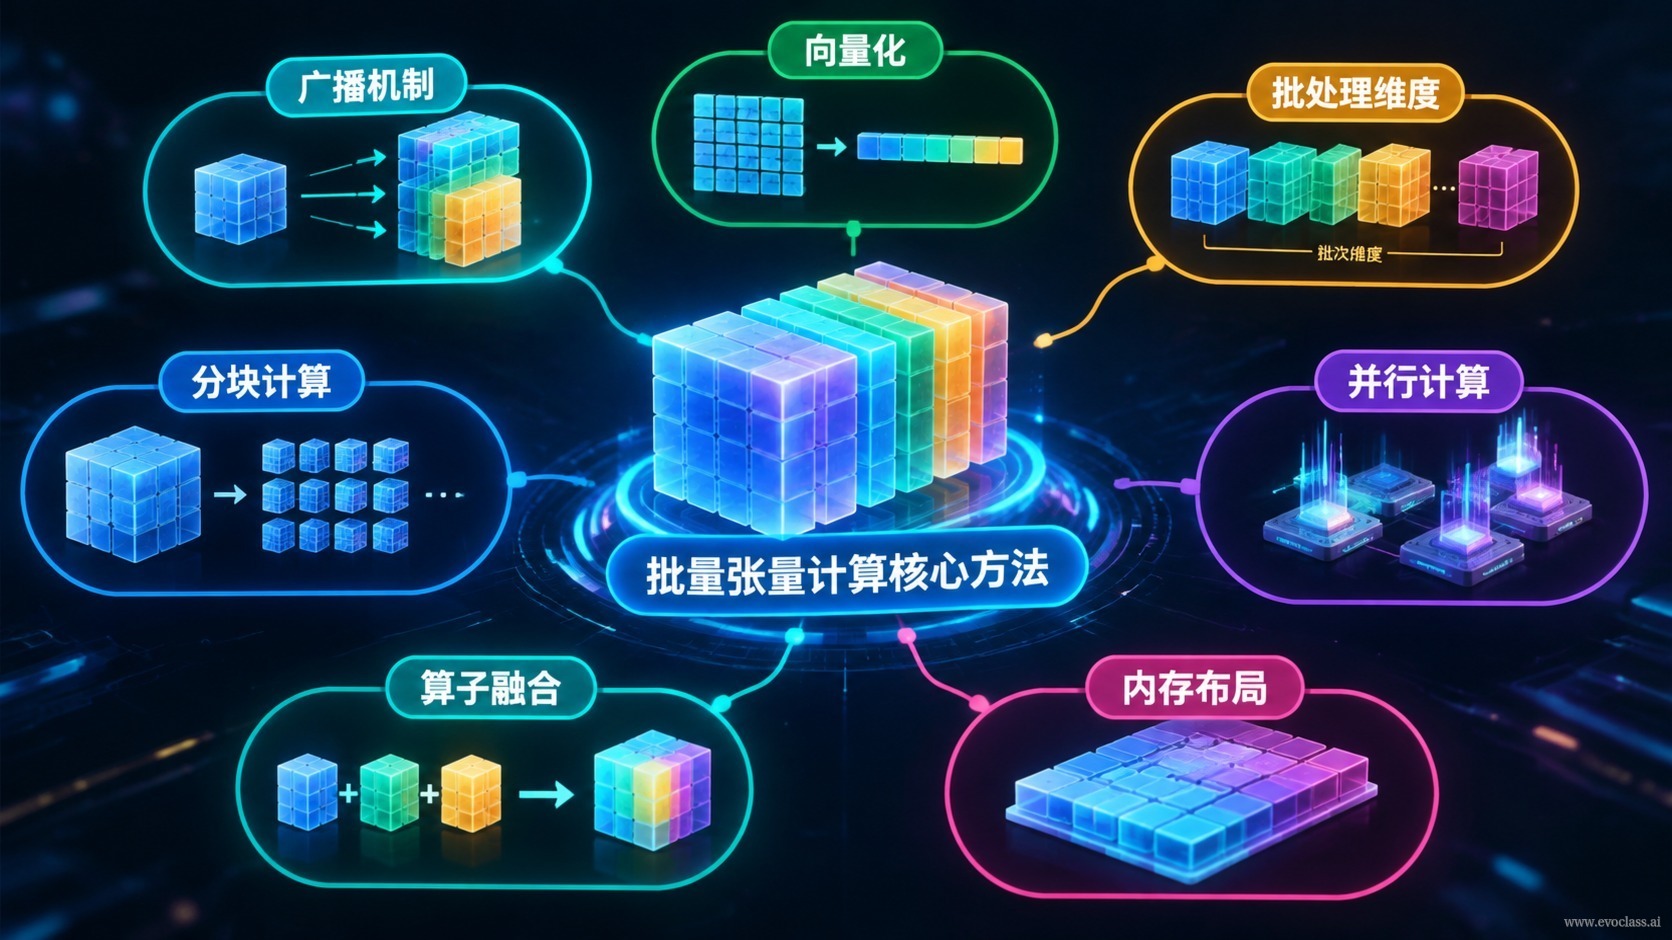
In the tensorized foundation of EvoX,batched tensor computationsits at the algorithmic expression layer: it uniformly maps the candidates, evaluations, and states within an evolutionary loop intotensors with a batch dimension, which are then executed by GPU-friendly batched operators and compiled computation graphs. The goal is crystal clear — transform "serial evolution, one individual at a time" into "parallel evolution of the entire population," so that compute power is truly applied to the search itself rather than consumed by scheduling and launch overhead.
1. Expressing the Evolutionary Process as Tensors
By convention, the batch dimension N represents the number of candidates (individuals), so the three core elements of evolution can be directly expressed as tensors:
- Candidate tensor: the population X is organized as [N × D], where D is the number of decision variables per candidate.
- Objective tensor: objectives and constraints F are organized as [N × M], where M is the number of objective/constraint terms; in the multi-objective case, each objective corresponds to a different column of F.
- State variables: generation count, current best values, step sizes, etc. are maintained in scalar or small-tensor buffers, rather than recorded per individual using Python objects.
In this way, crossover, mutation, selection, and evaluation are all batch-processed along the N dimension, and per-individual branches and control flow no longer appear in the evolutionary loop.
2. Batched Operators: From N Single-Candidate Calls to a Single Batched Operation
Three minimal comparable expressions outline the basic form of batched operators:
- Mutation: X′ = X + σ·randn(X), where the entire batch of candidates each receives a random perturbation in a single batched operation, with σ controlling the perturbation strength.
- Selection: idx = topk(F, k), which selects the indices of the top k candidates from the fitness values of N candidates in a single operation.
- Evaluation: Y = fθ(X), replacing N single-candidate calls with a single batched forward pass or batched simulation.
The key is not any particular operator, but that all candidates share a single tensor computation graph: one batched call can slash interpreter overhead and kernel launch overhead, allowing GPU/multi-core compute power to truly serve the evolutionary search. Constraint handling and out-of-bounds resolution can likewise be accomplished within the same batched operation using mask tensors, without branching separately for individual candidates.
3. Computation Graph Optimization and Throughput Metrics
Writing multi-generation evolution as a compilable dataflow graph can squeeze out even more performance:Operator Fusionreduces the number of kernel launches,Intra-batch Parallelismenables all candidates to execute simultaneously,Asynchronous Executionallows computation and data transfer to overlap,Memory Reusereduces intermediate tensor allocations. Accordingly, performance metrics should also shift from "per-step latency" tocandidates/sec or generations/secthroughput — under batched execution, a single call processes the entire batch of candidates, and only overall throughput truly reflects search efficiency.
Concept Map: Core Methods of Batched Tensor ComputationThe concept map expresses the evolutionary process as tensors with a batch dimension: population X is N×D, objectives and constraints F are N×M, and crossover, mutation, selection, and evaluation are all batch-processed along the N dimension. Mutation, topk selection, and batched forward evaluation each require only a single batched call, and performance metrics shift from per-step latency to throughput in candidates/sec.