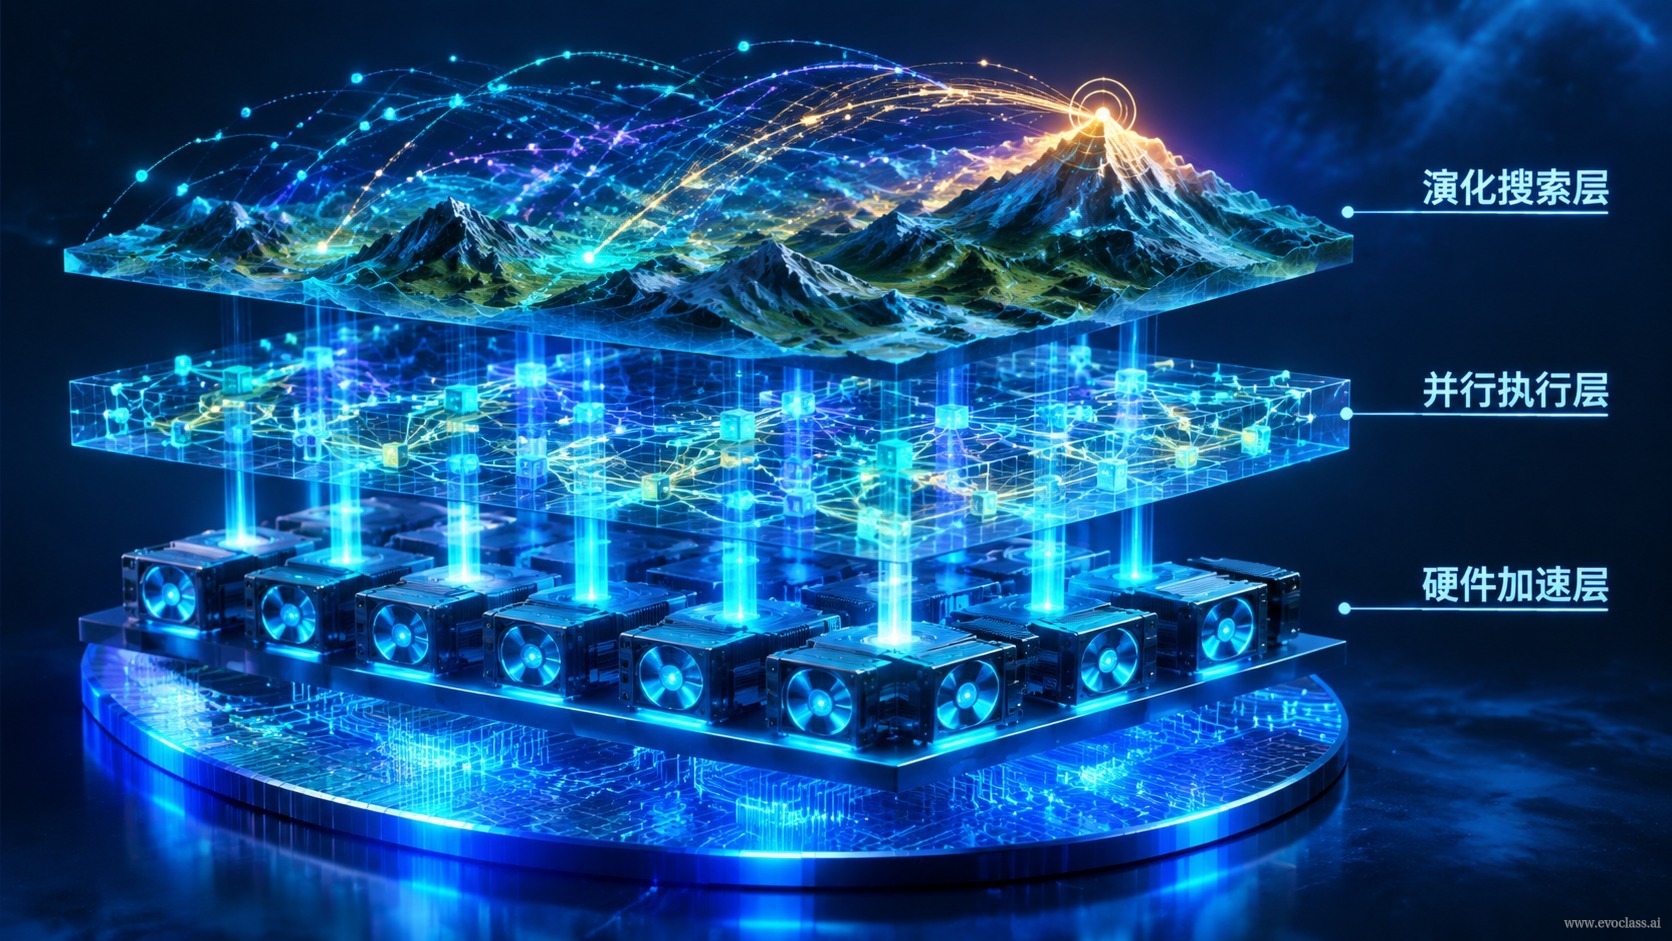
The reason EvoX can supporthigh-intensity parallel evolutionary explorationcomes down to a single statement:from candidate lists to tensorized computational graphs. Traditional evolutionary experiments treat each individual as an independent Python object, modeling and evaluating them one by one. When the candidate scale grows to thousands, the real bottleneck is often no longer the algorithm itself, but the per-candidate scheduling, synchronization, and I/O overhead. EvoX takes a different approach: it reorganizes the population, evaluation, and runtime state into tensors that can be computed as a whole, then dispatches them through a unified Runtime to GPUs and heterogeneous compute for batch execution—thereby supporting large-scale, multi-objective, multi-solution parallel evolutionary search.
Three Key Tensorization Targets
Tensorization is not a local optimization at a single point—it spans three levels of the evolutionary loop. If any one level falls back to per-object loops, parallelism will be bottlenecked there.
- Population tensorization: individual parameters, genes, or strategies are no longer looped over as separate Python objects, but are organized along thebatch dimensioninto tensors, with variation between individuals carried by one tensor dimension.
- Evaluation tensorization: fitness, constraints, multi-objective metrics, and simulation or model evaluation results can be computed in batches. Candidates within the same batch share a single device invocation, significantly reducing per-candidate scheduling and I/O overhead.
- State tensorization: runtime state such as generation count, random seeds, caches, and monitoring metrics is managed uniformly, so experiments remainreproducible and traceableeven after parallel acceleration.
Computational Graph Construction and Unified Architecture
Once candidate lists are elevated totensorized computational graphs, operator parallelism and compiler optimization have room to work: population size and evaluation parallelism can scale with compute, rather than being locked down by interpreter loops. Complementing this is a unified architecture—algorithms, problems, workflows and monitoring, and the Runtime scheduler are decoupled from one another: algorithms are composable, problems are pluggable, and heterogeneous compute is managed uniformly, so users need not worry about low-level scheduling while writing algorithms.
The most direct benefit of this foundation isBreaking through the serial bottleneck: it replaces traditional CPU serial loops with large-scale acceleration on GPUs and heterogeneous compute, providing a stable throughput base for high-intensity exploration. Within the same wall-clock time, one can explore more candidates, more objective combinations, or more random repetitions.
For example, suppose an evolutionary experiment needs to evaluate a large number of candidate solutions. The traditional approach calls the evaluation function one candidate at a time on the CPU, where scheduling, synchronization, and Python loops may dominate the runtime. EvoX sends candidate matrices to the device in batches, with the Runtime dispatching operators and evaluations and uniformly recording state and monitoring metrics, enabling more candidates, more objective combinations, or more random repetitions within the same wall-clock time. This is precisely the engineering support needed when real-world multi-objective problems—such as supercritical airfoil design, where cruise lift-to-drag ratio and critical buffeting lift coefficient constrain each other—require retaining a diverse set of candidate solutions.
EvoX Modern Compute Foundation — Full Ecosystem OverviewThe diagram summarizes the EvoX foundation as an upgrade from candidate lists to tensorized computational graphs: the three layers—population, evaluation, and runtime state—are unified through tensorization, then dispatched by the Runtime to GPUs and heterogeneous compute for batch execution. This decouples algorithms, problems, workflows, and monitoring from one another, so parallelism is not bottlenecked by per-candidate loops as compute scales, and more candidates and objective combinations can be explored within the same wall-clock time.