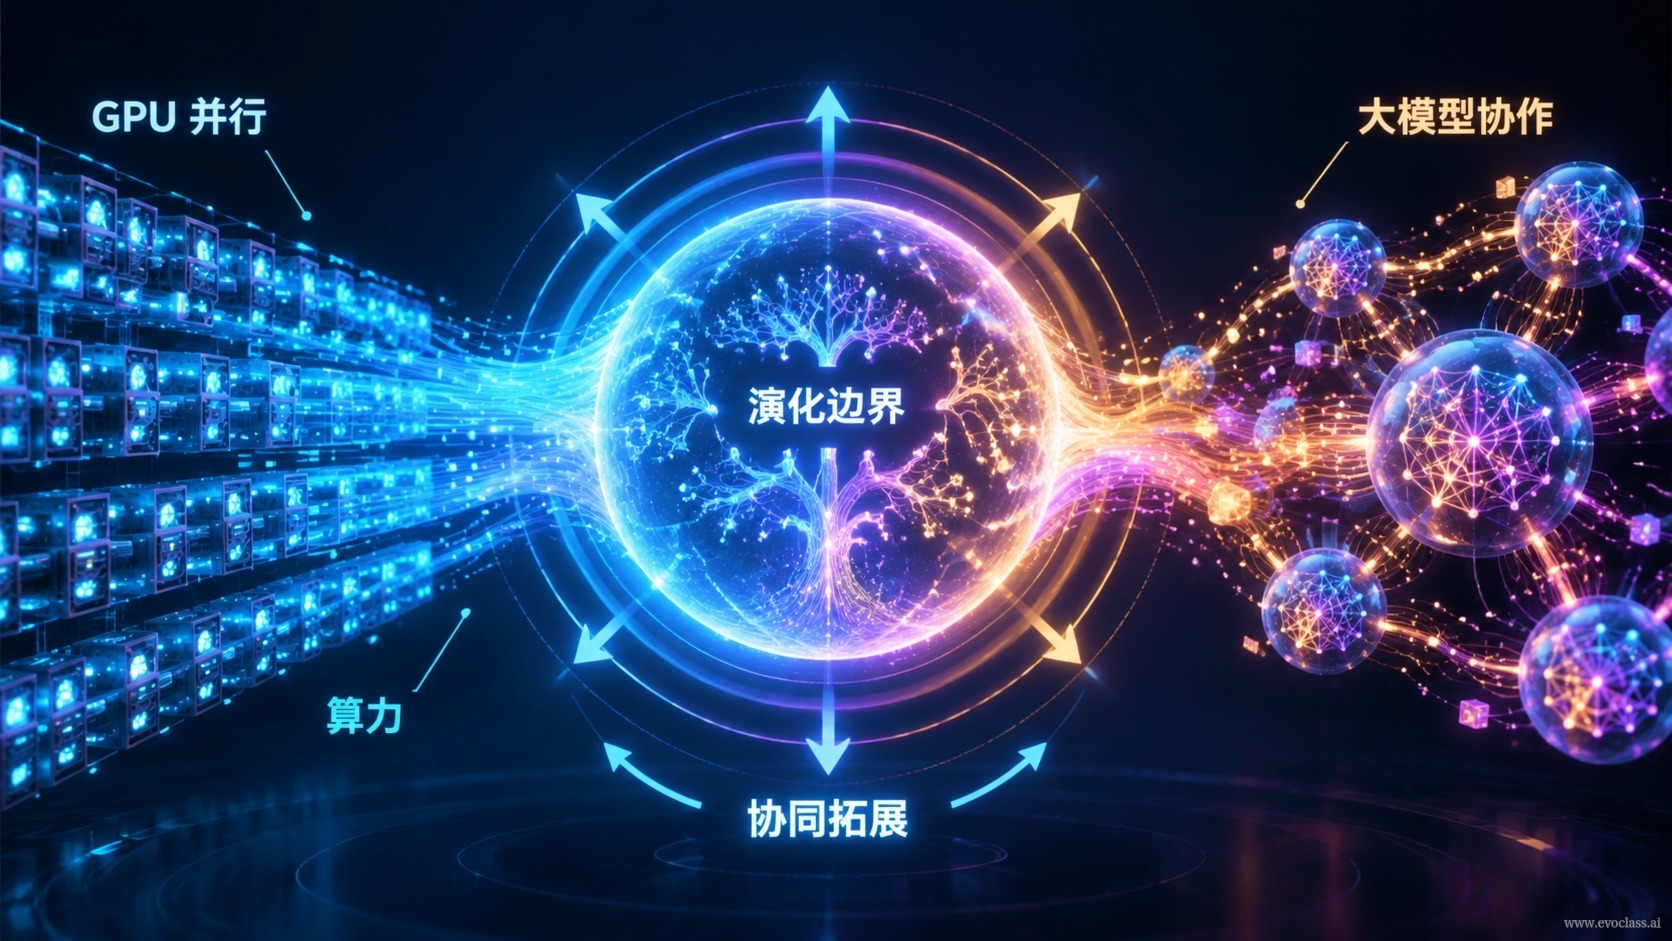
Evolutionary computation has long been constrained by a practical question: how many candidates can actually be evaluated within a limited time. Today, this constraint is being loosened simultaneously by two engineering forces—GPU parallel computeandlarge-model semantic generation. Together they form the dual engineering foundation of evolutionary computation:compute determines “how many candidates can be explored at once,” while large models determine “what forms of candidates can be explored”, and together they push the boundary of evolutionary objects beyond numerical parameters to programs, model structures, and algorithmic mechanisms themselves.
The compute foundation: moving candidate space from serial loops to tensors
In traditional implementations, population evaluation is a serial loop on the CPU: only one individual is processed at a time, and scheduling overhead accumulates with population size. Open-source foundations such as EvoX organize candidates, evaluation results, and algorithm states uniformly astensors that can be computed as a whole: mutation acts on the entire population, and evaluation and state updates, together with selection, enter the computation graph for compiler optimization. The direct engineering result is that “exploring tens of thousands of candidates simultaneously” has gone from a laboratory trick to standard practice.
Such foundations divide the system into algorithms, problem modules, workflows, and a Runtime scheduler: researchers only need to focus on “how to evolve,” while the Runtime handles scheduling batch computation to GPUs, accelerators, or distributed clusters. What must be clearly understood is that compute solvesthroughput, not “intelligence.” It does not judge whether candidates are good; it is only responsible for computing the fitness of the entire population in one pass. It is theunderlying supportfor expanding candidate space, but it does not determine what candidates look like.
The semantic foundation: raising candidate form from numerical vectors to structural solutions
The contribution of large models is not faster computation, but that they understand code, domain knowledge, and task context, and possesssemantic-level generation capability. As a result, they can construct structurally complex candidates—a piece of directly callable solver code, the topology of a surrogate model—rather than only outputting a numerical vector. The “form” space of candidates is thereby opened up.
The three-level expansion of evolutionary object boundaries
- Numerical parameters: the classic setting, where population members are a set of parameter values under a fixed structure.
- Program / model structure: population members become executable code snippets, or the topology of networks and surrogate models. Large-model generation capability is precisely the gateway to this level.
- Algorithmic mechanisms: even the process of “how to generate and how to evaluate” itself becomes an object of evolution. This is precisely the premise that makes later approaches of “using evolution to improve evolution” (such as MetaDE and AutoPSO) possible.
Take airfoil optimization as an example: traditional approaches can only search over a number of preset numerical parameters; when a large model can read and write solver code and construct surrogate model structures, and the GPU can evaluate an entire population in parallel batches, the search object shifts upward from “a set of parameter values” to “a generation-and-evaluation scheme itself.”
Complementary, not substitutive
The two are complementary: compute expands searchBreadth, while large models improve candidatequality and formal complexity; without either one, boundary expansion does not hold. With only compute and no semantic generation, the search object remains confined to pre-hardcoded encodings; with only generation capability and no batch evaluation, massive candidates cannot be screened within an acceptable time.
The cost of expanding boundaries
Expanding boundaries also introduces new constraints: first,evaluation cost rises, as a single evaluation may go from milliseconds to minutes; second,correctness verification becomes harder, since generated code may fail to compile or may not satisfy physical and engineering constraints; third,the criteria for what counts as a “usable answer” become more ambiguous, requiring integration with multi-objective trade-offs, expert decision-making, and other stages.
Flowchart: GPU Parallelism and Large Models Collaboratively Expanding Evolutionary BoundariesThe diagram shows that expanding evolutionary boundaries depends on a dual foundation: GPUs and a tensorized Runtime move population evaluation from serial loops to batch parallelism, determining how many candidates can be explored at once; large models provide semantic-level generation, determining what forms of candidates can be constructed. Once the two complement each other, evolutionary objects can expand from numerical parameters to program/model structures, and further to algorithmic mechanisms—but this also brings new constraints such as evaluation cost, correctness verification, and criteria for judging answers.