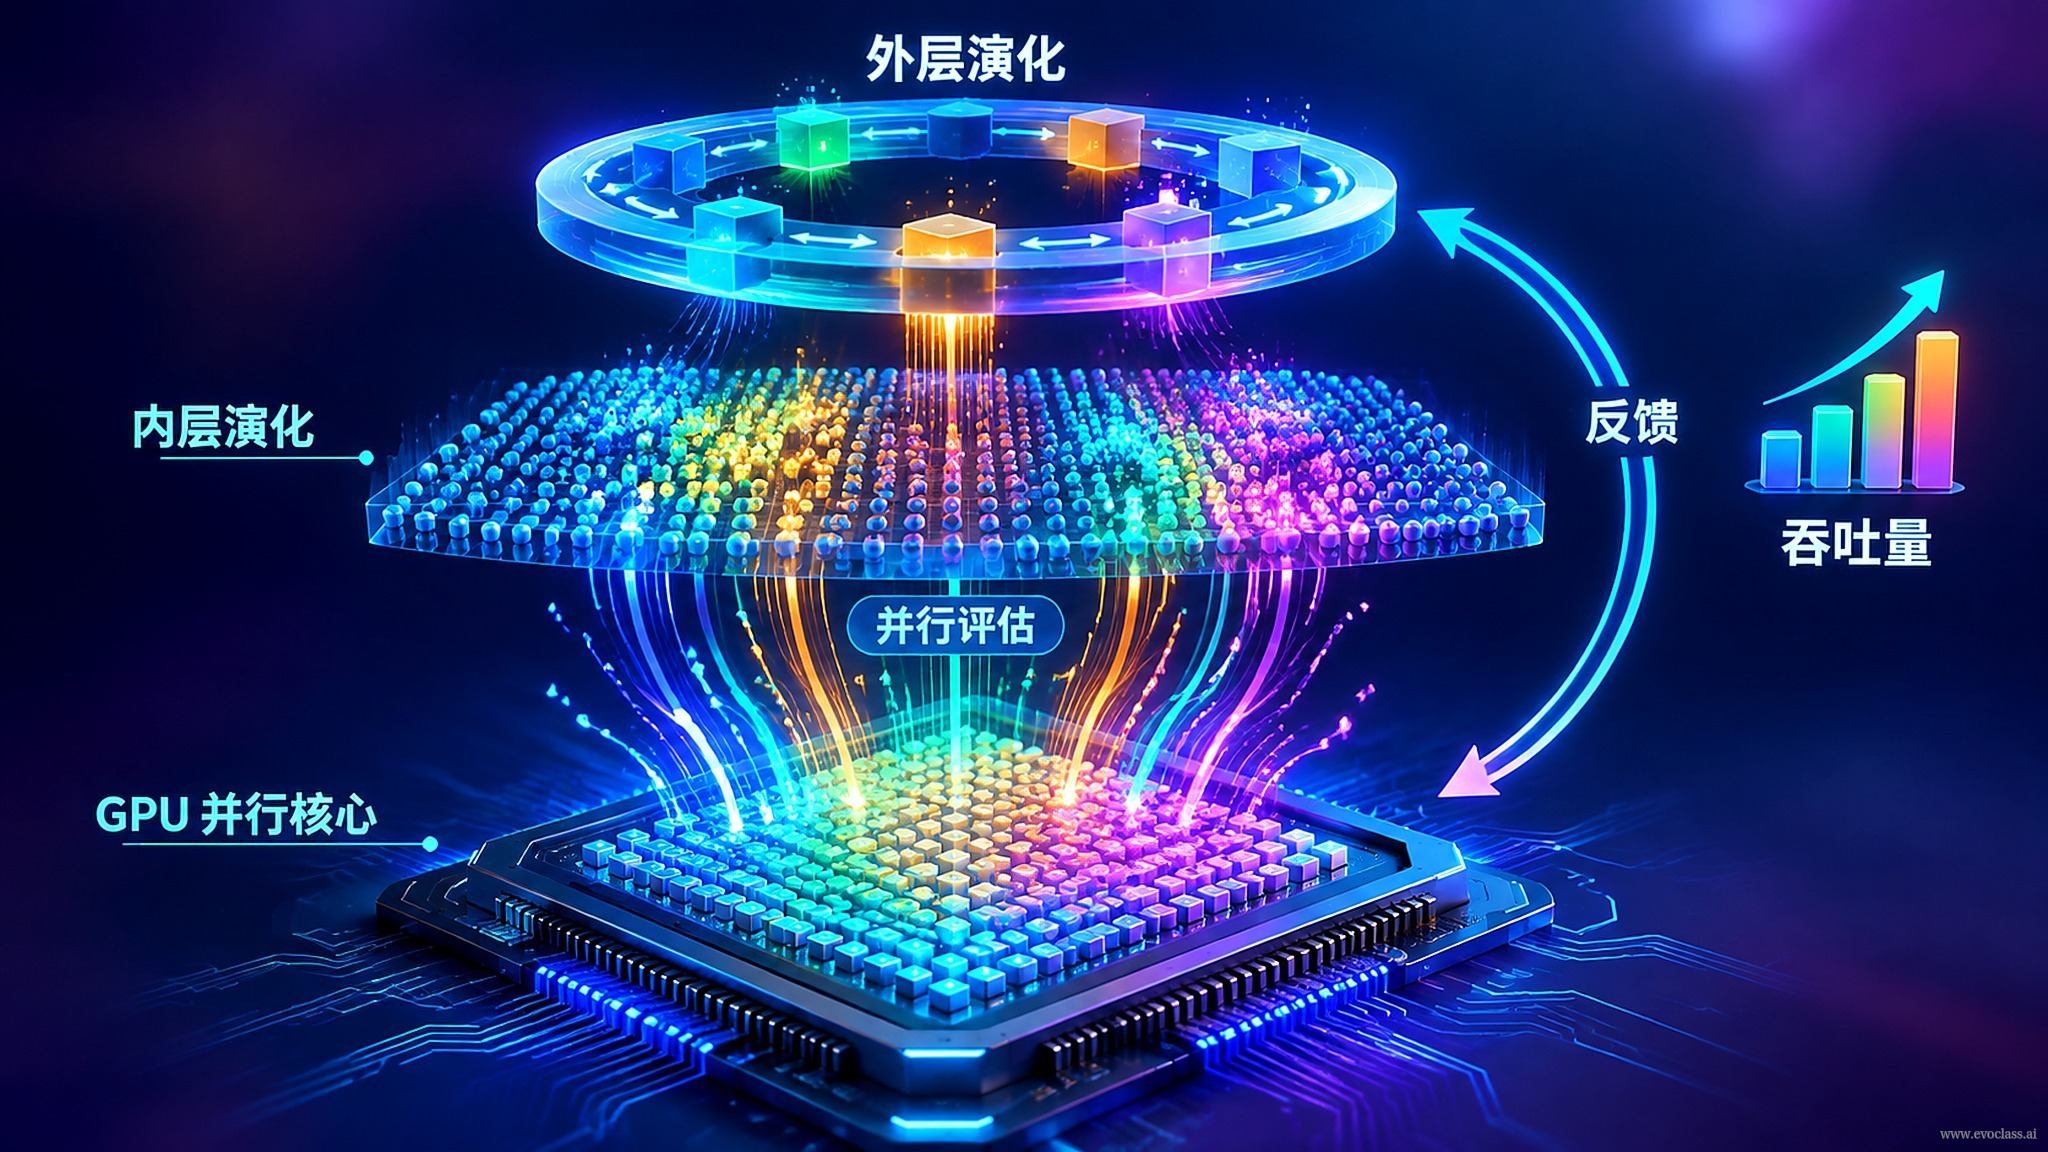
When evolutionary algorithms are used toimprove evolutionary algorithms themselves, two layers of computation coexist in the system: the inner layer executes and evaluates a large number of algorithm configurations across many task instances, while the outer layer selects, mutates, and updates configurations based on these run results. Without a powerful parallel foundation, outer-layer evolution would be bottlenecked by the inner layer's serial evaluation.GPU parallelismis precisely what turns "improving evolution with evolution" from a theoretical concept into a high-throughput, executable process: inner-layer tasks run in parallel batches and continuously produce performance data, and outer-layer evolution uses this data as feedback to keep selecting better algorithm configurations.
Each Layer Plays Its Part
- Inner layer (execution and evaluation): Batch-executes a large number of candidate algorithm configurations (with different hyperparameters, operators, or search strategies) on the GPU, running and scoring each on every task instance. The tasks are fine-grained and numerous, which perfectly matches the GPU's batch-throughput characteristics.
- Middle layer (feedback aggregation): Aggregates the raw performance of massive inner-layer tasks into statistical metrics, estimating how well each configuration performs across the entire task distribution to form the fitness used by the outer layer.
- Outer layer (configuration selection): Takes statistical feedback as input to perform selection, mutation, or updates, generating the next generation of configurations and sending them back to the inner layer, forming a closed loop.
Why GPU Parallelism Is Irreplaceable
Under a traditional serial loop, the wall-clock time of a single iteration is jointly determined by "number of candidate configurations × number of task samples," which becomes prohibitive at even modest scale—making the serial loop the main bottleneck limiting candidate configurations and task sample size. GPU parallelism lets a large number of inner-layer algorithms run simultaneously, reducing the serial loop from the "main bottleneck" to "acceptable batch-processing overhead," thereby amplifying both the explorable configuration space and the task sample size.
Core Mechanism: One Closed Loop
The entire system can be summarized as a loop of "inner-layer task parallel throughput → performance feedback aggregation → outer-layer configuration selection" : the higher the parallelism, the more abundant the feedback samples, the more stable the outer layer's fitness estimates, and the more reliable the direction of configuration improvement; the improved configurations are then sent back to the lower layer for the next round of parallel throughput. It is precisely this closed loop that gives the algorithm the ability to continuously self-optimize and turns "improving evolution with evolution" from a theoretical concept into an efficient, executable process.
GPU-Parallel Two-Layer Evolutionary Throughput ArchitectureThe diagram shows a closed loop: the inner layer batch-executes and scores a large number of candidate algorithm configurations on the GPU, the middle layer aggregates the massive inner-layer performance into statistical metrics and forms fitness, and the outer layer uses this to select, mutate, and generate the next generation of configurations, which are then sent back to the inner layer. The higher the parallelism, the denser the feedback samples, the more stable the outer layer's estimates of configuration quality, and the serial evaluation bottleneck is likewise reduced to acceptable batch-processing overhead.