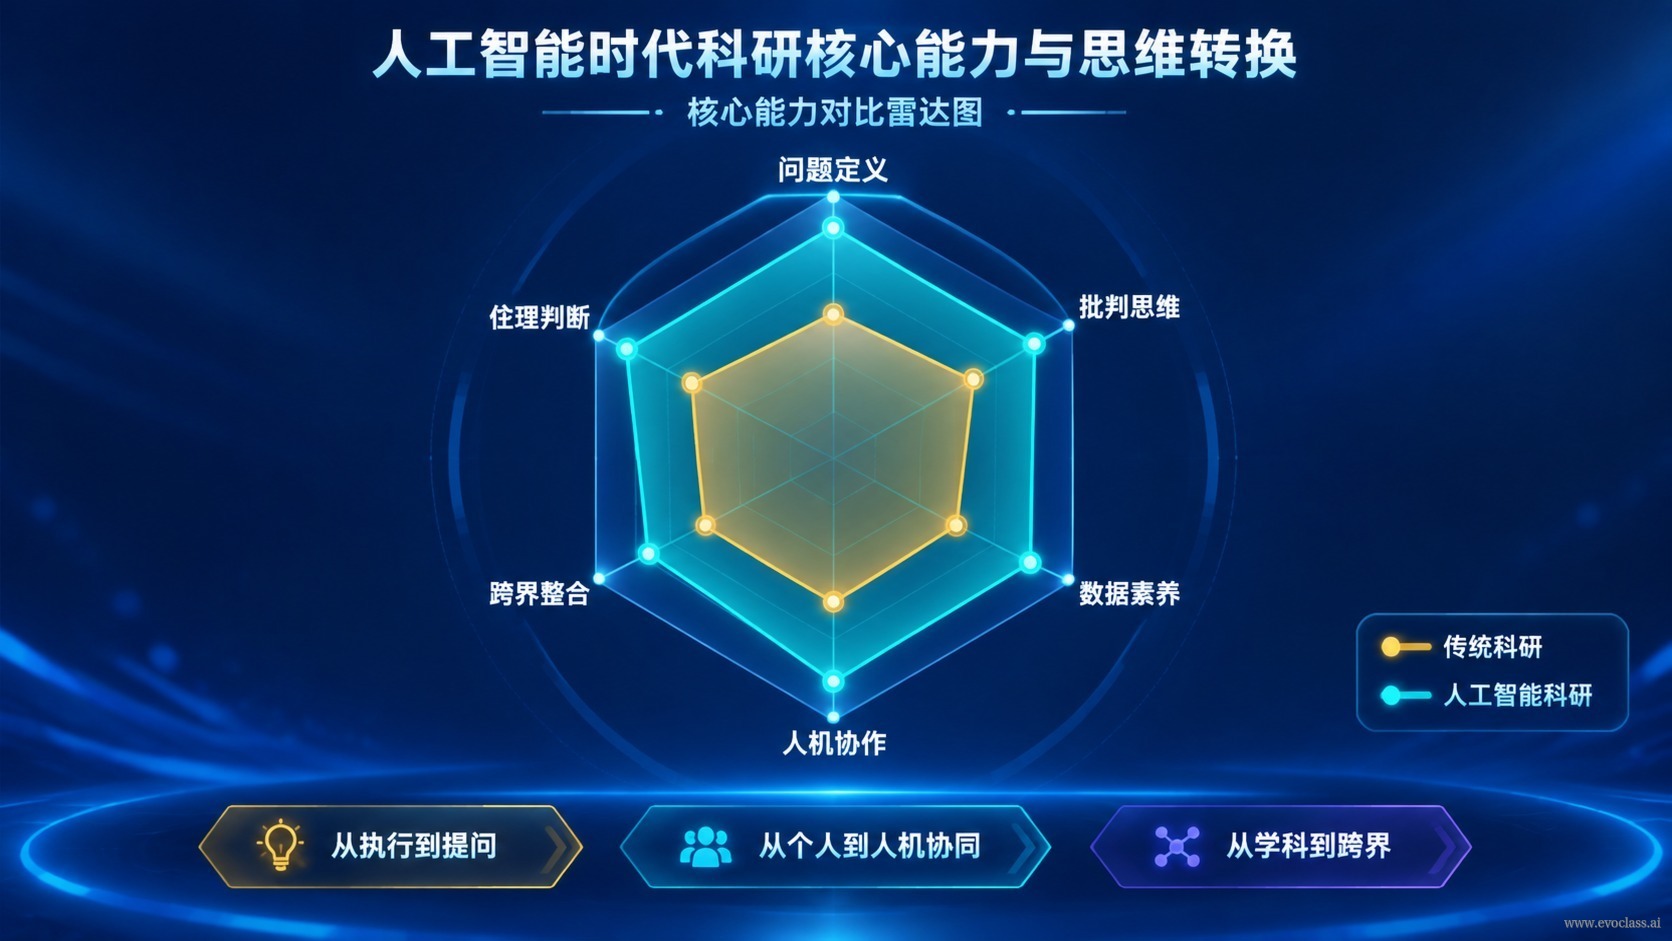
In AI-assisted research, a researcher's core competencies are undergoing ashift in mindset: where we once measured ability by whether we could write the implementation ourselves, code and experiment scripts can now be generated rapidly by AI. What's truly scarce is the ability to ask the key questions, define evaluation and fair-comparison criteria, and exercise critical judgment over the evidence AI produces.
Role Shift: From Implementer to Evidence Arbiter
When the cost of implementation drops sharply, the researcher's role moves up from "implementer" toproblem definer, experiment designer, and evidence arbiter. AI takes on the job of turning ideas into runnable answers, while "which questions are worth answering and which evidence is worth trusting" remains the researcher's call.
- Problem Definer: judging which kinds of problems carry scientific value, rather than which are easiest to produce results for.
- Experiment Designer: turning vague ideas into executable, reproducible, and comparable experimental protocols.
- Evidence Arbiter: staying skeptical of the curves, metrics, and conclusions AI provides, and probing their limits of credibility and failure conditions.
Three Key Questions Only Humans Can Answer
- What to Change: Is this change at the level of optimization parameters, program implementation, algorithmic structure, or the research workflow itself? The level of change determines entirely what the conclusion means.
- Evaluation Feedback: Which metrics to observe, what proxy signal approximates the true objective, where the acceptance threshold lies, and under what conditions to declare failure—none of the four can be omitted.
- Fair Comparison: Whether baselines, budgets, randomness, compute conditions, and statistical tests are aligned. Misaligned comparisons often mistake random fluctuations or compute advantages for algorithmic progress.
Why "Taste" Matters
AI can generate plenty of "working" solutions, but feasible doesn't mean valuable.Taste matters: among numerous feasible options, judging which problem, which hypothesis, and which piece of evidence truly carries scientific value—this is precisely the human researcher's core value. Accordingly, the focus of competency shifts from raw coding speed to critical thinking, systems abstraction, domain judgment, and human-AI division of labor.
Core Competency ShiftThis chart uses a competency comparison to illustrate how the focus of research skills is shifting in the AI era: when implementation can be produced rapidly, a researcher's more critical value lies in asking the key questions, designing reproducible experiments, judging the boundaries of evidence, and ensuring fair alignment of baselines, budgets, and statistical tests.