Traditional evolutionary computation focuses primarily on low-dimensional, predefined numerical parameter vectors—such as hyperparameters, weights, and continuous variables—with search spaces constrained by manually predefined structures and encodings. As computational scale and engineering infrastructure expand, searching over high-dimensional, discrete, and structured objects shifts from infeasible to tractable, and the search boundary expands in step with compute power and toolchains.
On this basis, large models bring code understanding, contextual reasoning, and candidate generation capabilities, enabling them to directly construct, modify, and evaluate program-level objects while reducing reliance on hand-designed encodings and mutation operators. Once compute scale opens up, if the method for producing candidates remains manually fixed in advance, the system can only repeat established patterns; bringing the candidate-generation method itself into the evolutionary object (for example, the mutation strategy and parameter settings in differential evolution) is a direct manifestation of this boundary expansion at the methodological level.
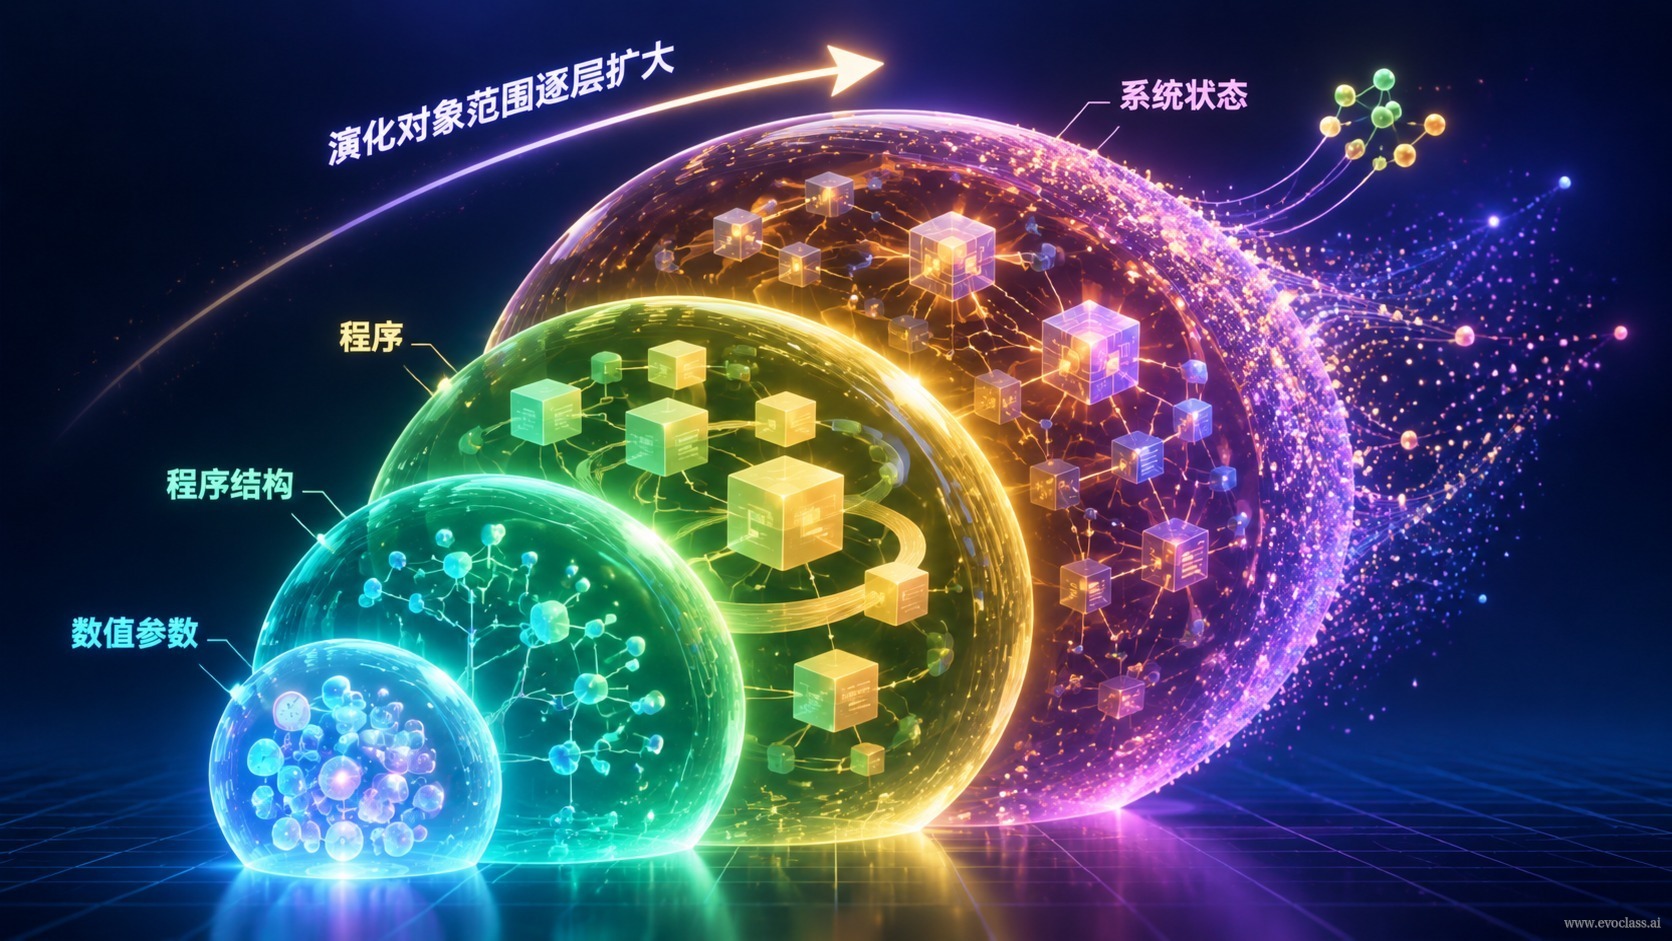
The figure below shows the structure of this hierarchical expansion.
As a result, evolutionary objects exhibit hierarchical expansion: numerical parameters → model architecture → algorithm mechanisms → program and software engineering state. The higher the level, the stronger the semantic constraints and the longer the evaluation chain: candidates must be executable and verifiable, and fitness evaluation shifts from a scalar function to a joint judgment combining runtime results with engineering constraints. This expansion does not replace parameter optimization; rather, it absorbs parameter optimization into a broader program and system evolution loop, forming a continuous spectrum from local tuning to system-level improvement.
Hierarchy diagram of evolutionary objects expanding from numerical parameters to program systemsThe diagram shows the hierarchical expansion of evolutionary objects from bottom to top: numerical parameters, model architecture, algorithm mechanisms, and finally program and software engineering state. The higher the level, the stronger the semantic constraints and the longer the evaluation chain. Candidates must be executable and verifiable, and fitness shifts from a scalar function to a joint judgment combining runtime results with engineering constraints—thereby absorbing parameter optimization into a broader program evolution loop.