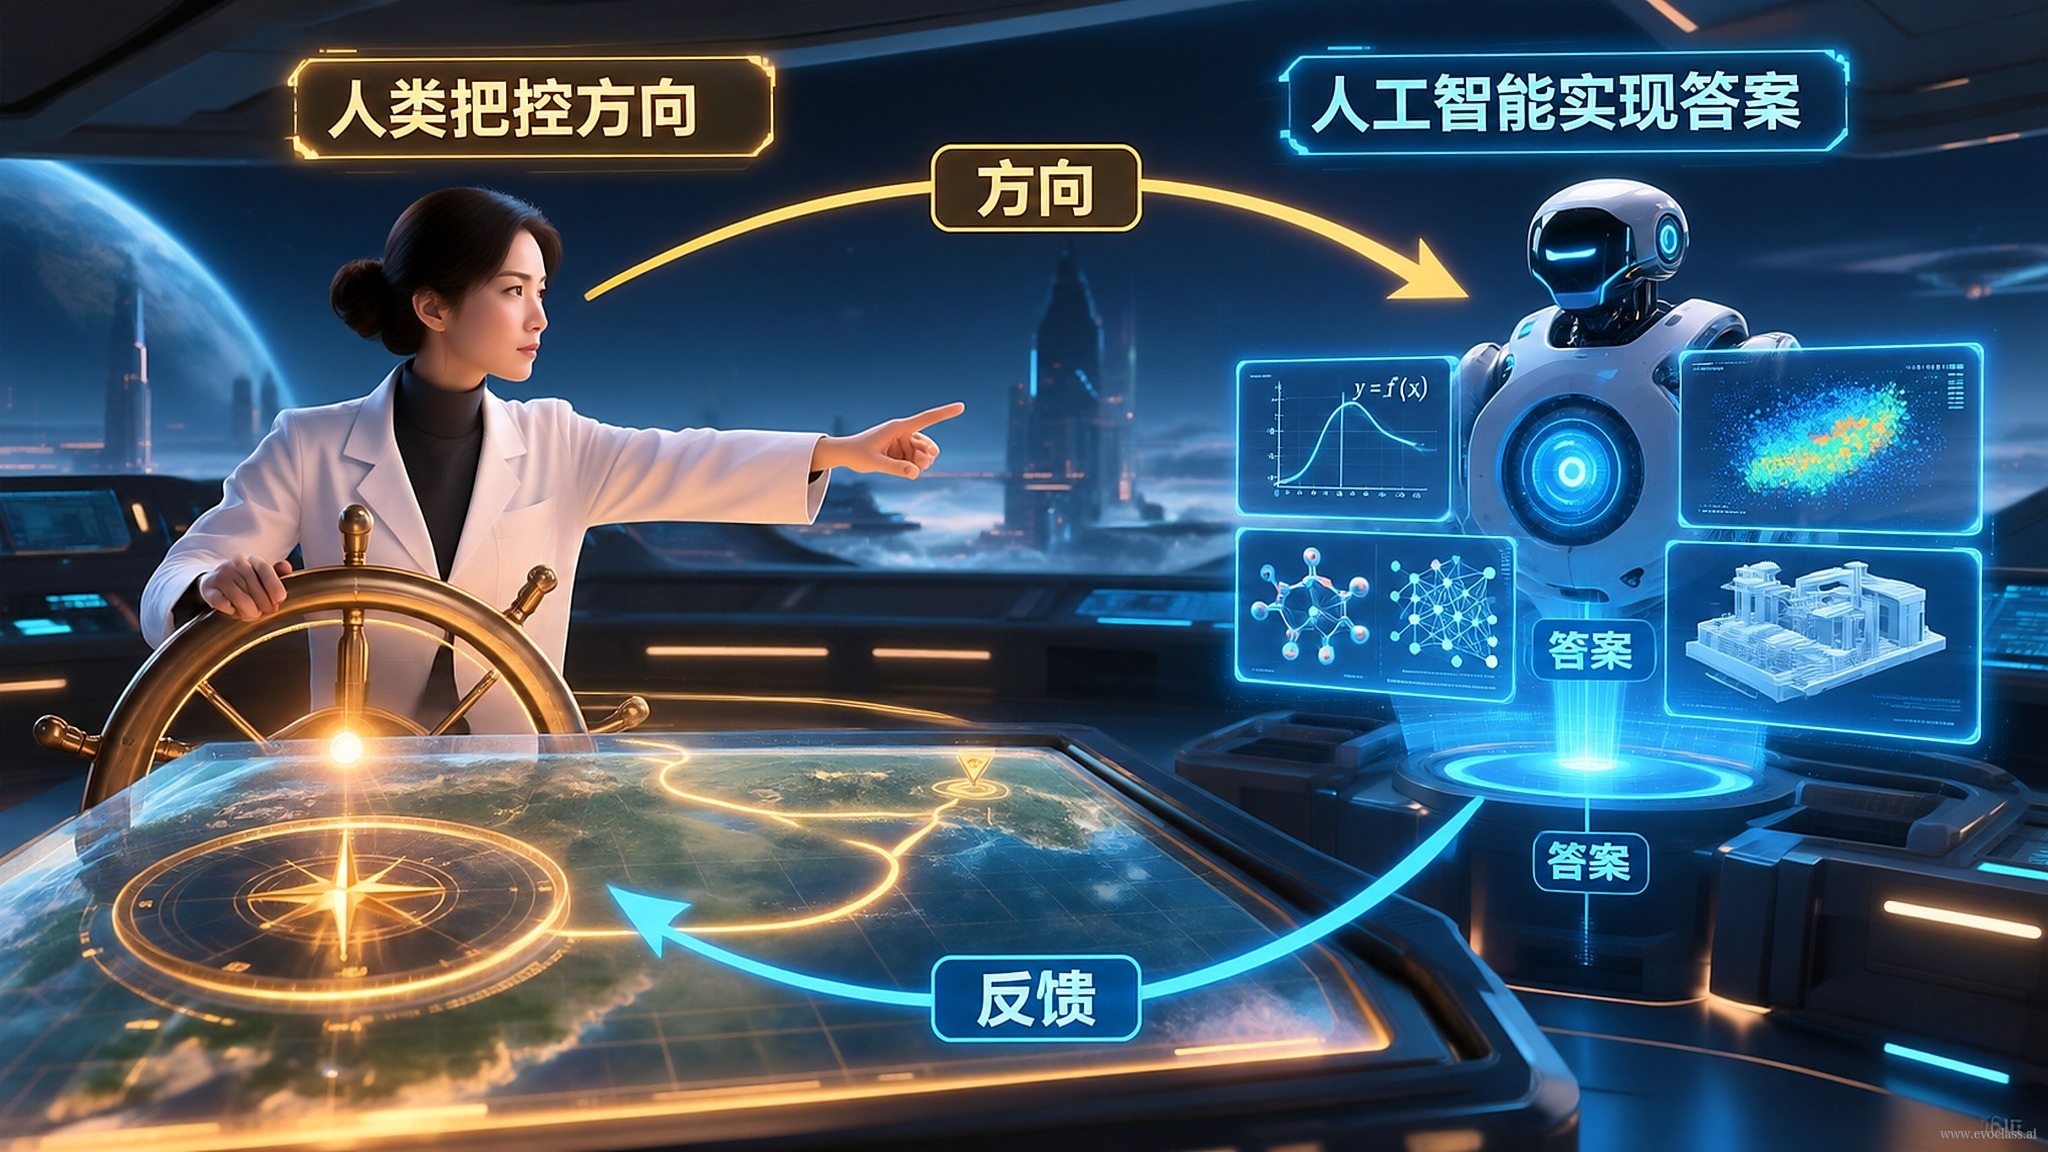
In real research and engineering systems, AI's most underrated capability isn't "thinking deeper" — it'sexpanding the bandwidth of implementation and exploration to a scale beyond human reach. The essence of human-AI division of labor can therefore be drawn as a clear dividing line: hand overimplementation and explorationto AI, and leavedirection and judgmentto the researcher. AI rapidly generates answers, runs experiments in batches, searches candidate solutions, and reports results back; humans decide which questions are worth answering, which evidence is trustworthy, and ensure the results carry genuine scientific significance.
The AI Side: Driving Implementation Cost Down to Nearly Zero
- Rapidly implement answers: Once the problem and evaluation criteria are clearly defined, AI can deliver runnable, verifiable solutions and explanations in a very short time — implementation is no longer the bottleneck.
- Run experiments in batches: The same pipeline can be scaled to hundreds or thousands of parallel trials, turning "trial and error" from a scarce resource into routine practice.
- Search candidate solutions and report back: Generate, filter, and collect results across vast search spaces, extending exploration into territories human effort alone cannot reach.
The Human Side: Keeping the Cost of Judgment in Your Own Hands
- Ask the key questions: Decide which questions are worth answering, rather than casually answering an easy one.
- Define goals, constraints, and evaluation criteria: Check whether the optimization objectives, constraints, and evaluation metrics truly capture the real-world problem.
- Judge whether the evidence is trustworthy: Distinguish "results that run" from "results that are reliable," and identify overfitting, data leakage, and metric gaming.
- Scientific significance acceptance: The final deliverable is not more numbers, but conclusions that stand up scientifically and are worth further investment.
Why a Closed Loop Is Essential
The two sides are coupled through "results flowing up and standards flowing down": AI pushes candidate answers and experimental feedback to the researcher, and the researcher hands goals, constraints, and acceptance criteria back to AI. The value of the closed loop lies in this:AI expands exploration bandwidth, humans control direction and acceptance criteria. If either side is missing, the loop breaks down — with only AI, you get a flood of meaningless results; with only humans, exploration bandwidth is limited. Take multi-objective evolutionary exploration as an example: AI can automatically generate and run a large number of candidate solutions, while the researcher decides whether the optimization objectives, constraints, and evaluation metrics reflect the real problem, and selects the scientifically credible directions worth exploring further.
Self-check:Recall your most recent experiment: who made the judgments "should we tackle this problem" and "what counts as success"? If the answer is the model for both, the division of labor has already broken down.
The Human-AI Division of Labor LoopThis division-of-labor model assigns to the AI side: rapidly implementing answers, running experiments in batches, searching candidate solutions, and reporting results. To the human side: asking the key questions, setting goals, constraints, and evaluation criteria, judging whether evidence is trustworthy, and accepting scientific significance. The two sides form a closed loop through results flowing up and standards flowing down. If the evaluation criteria are also handed to AI, the system will efficiently optimize an objective that doesn't reflect the real scientific problem.